GPT-6.1 Sol vs. GPT-6.2 Sol
The new version GPT-6.2 Sol against the older GPT-6.1 Sol on the same 5 zero-shot prompts – what changed in function, looks, cost and time.
Short answer
- In our test GPT-6.1 Sol had the better result in 2 and GPT-6.2 Sol in 2 of 5 prompts, 1 tied.
- Ran on the first attempt: GPT-6.1 Sol 5/5, GPT-6.2 Sol 4/5.
- Average score: GPT-6.1 Sol 93/100, GPT-6.2 Sol 76/100 (a broken output = 0).
- Cost of all prompts: GPT-6.1 Sol $1.08, GPT-6.2 Sol $0.93.
- Total generation time: GPT-6.1 Sol 31 min 54 s, GPT-6.2 Sol 17 min 16 s.
- GPT-6.2 Sol is better at: New York & Central Park map, Chess with an engine; worse at: Solar System, GTA-style game.
Tested 15 Oct 2026 – 18 Nov 2026, one attempt per prompt and model; the table shows the original outputs (a fixed copy is listed separately). This is the result of our test, not a general measure of the models' reliability. Time = from sending the prompt to the last token of the answer, thinking included (for runs in Claude Code the whole task incl. writing the file), fixes excluded. Cost = tokens × the public API price list as of the date at the model, fixes excluded; ≈ = an estimate when only the token total is known. It is not the amount actually paid – subscriptions, caching or discounts change it.
Editor's note
GPT-6.2 Sol met every requirement (8/8) on four prompts in this test – the New York map improved from 7.5 to 8/8 – but its GTA game did not start on the first attempt (a variable named top collides with window.top), so it scores 0 there; the fixed copy by the same model met 8/8. GPT-6.1 Sol had all five outputs working on the first attempt. The new version generated faster (about 17 versus 32 minutes in total) at a similar cost ($0.93 versus $1.08).
Results per prompt
| Prompt | GPT-6.1 Sol | GPT-6.2 Sol | Better result | Cost A / B | Time A / B |
|---|---|---|---|---|---|
| Solar System | 8/8 Score 94/100 | 8/8 Score 93/100 | GPT-6.1 Sol | $0.21 $0.17 | 4 min 53 s 3 min 11 s |
| GTA-style game | 8/8 Score 92/100 | broken original = 0 points fixed copy: 8/8 | GPT-6.1 Sol | $0.26 $0.20 | 8 min 19 s 3 min 40 s |
| Monitor test | 8/8 Score 96/100 | 8/8 Score 96/100 | tie | $0.12 $0.13 | 3 min 30 s 2 min 27 s |
| New York & Central Park map | 7.5/8 Score 88/100 | 8/8 Score 91/100 | GPT-6.2 Sol | $0.21 $0.27 | 6 min 54 s 5 min 04 s |
| Chess with an engine | 8/8 Score 94/100 | 8/8 Score 99/100 | GPT-6.2 Sol | $0.29 $0.16 | 8 min 18 s 2 min 54 s |
Better result = higher overall score of the original output (60 % requirements, 30 % UX / UI, 10 % technical health). Cost by the API price list as of the date at the model, ≈ = estimate. Time = from sending the prompt to the last token of the answer, thinking included (for runs in Claude Code the whole task incl. writing the file), fixes excluded. Cost = tokens × the public API price list as of the date at the model, fixes excluded; ≈ = an estimate when only the token total is known. It is not the amount actually paid – subscriptions, caching or discounts change it.
Previews and reviewers' verdicts
Output previews – click to open them live. The text under a preview is the summary of the published review.
Solar System
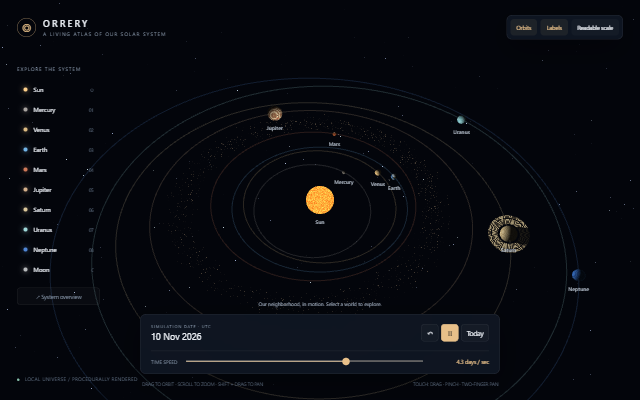
Score 94/100
A very solid, compact WebGL orrery with real orbital elements and complete controls. Only minor nit is some moire on Saturn's rings.
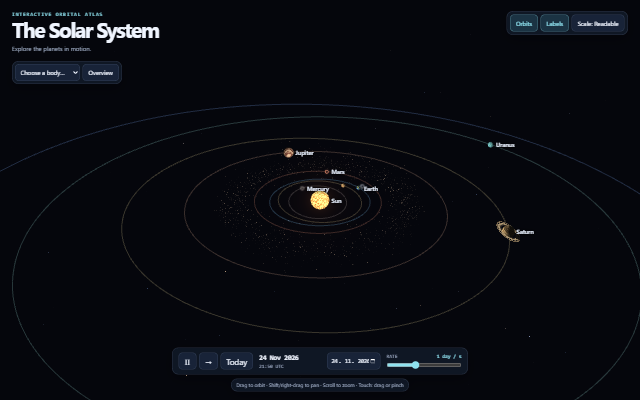
Score 93/100
An accurate WebGL orrery with Kepler orbits, a lunar theory with perturbations, a date picker and true scale for distances and sizes.
GTA-style game
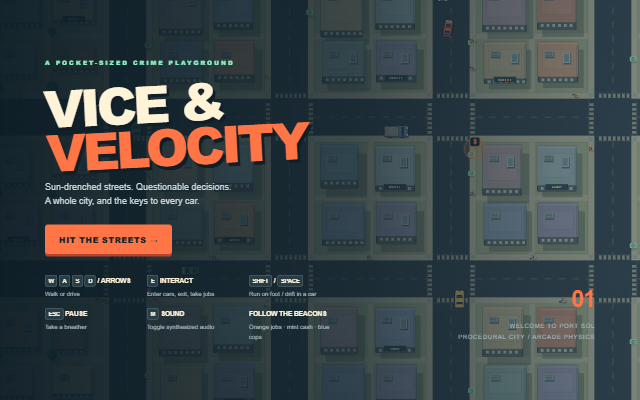
Score 92/100
A very complete top-down GTA-like game covering every requirement with working logic. Police AI is simple but escalates, and the whole feels polished.
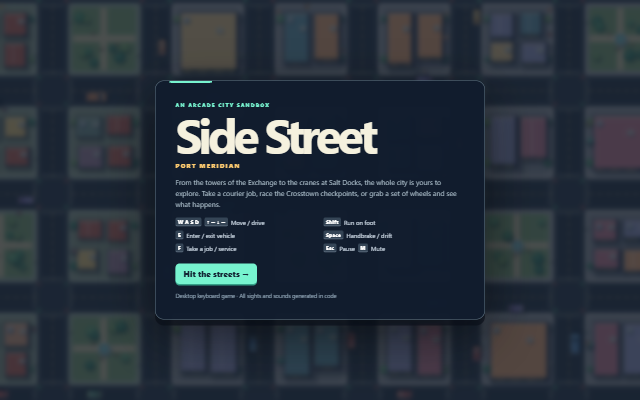
fixed copy: 8/8
The original output did not run and counts as 0 points. The preview and verdict below belong to a fixed copy by the same model (8/8) – it does not count in the comparison.
Verdict of the fixed copy: Fixed version: a full game with 4 vehicles, damage, fleeing pedestrians, escalating police, two missions and a minimap.
Monitor test

Score 96/100
A compact, complete monitor test tool; every requirement is correctly implemented with care for device-pixel accuracy. Tests are simple but functional.
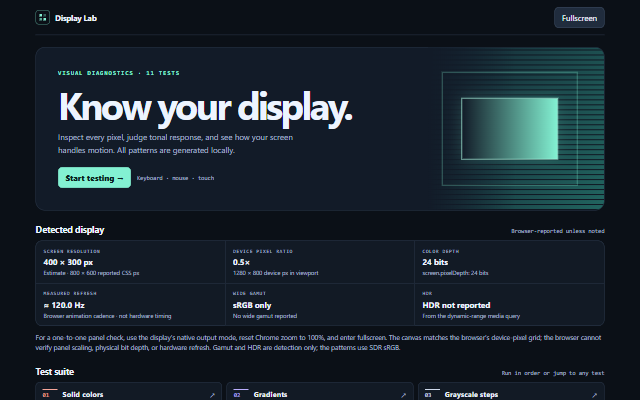
Score 96/100
A complete suite of 11 tests with exact pixels, an adjustable gamma and detailed help; mouse, keyboard and touch control.
New York & Central Park map
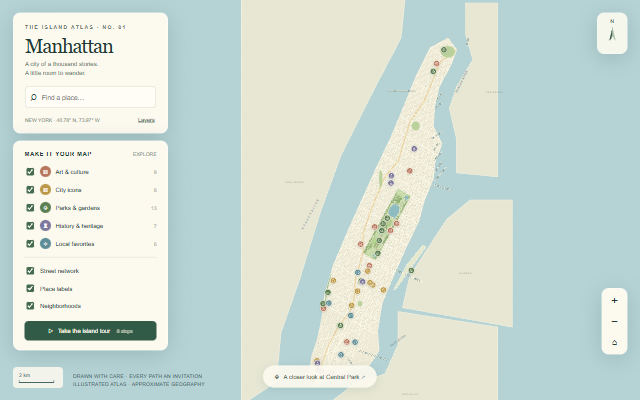
Score 88/100
A nicely illustrated, content-rich Manhattan map with detailed Central Park and a guided tour. Main flaw: pointer capture on the SVG likely blocks opening info cards by clicking landmarks.
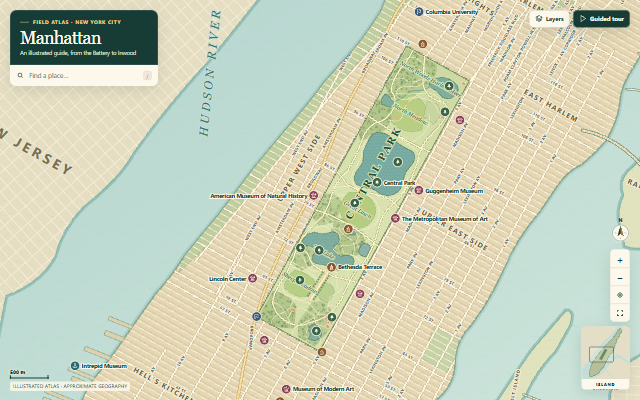
Score 91/100
A rich illustrated map with 73 places in 6 categories, a detailed Central Park, minimap, compass, search and a guided tour.
Chess with an engine
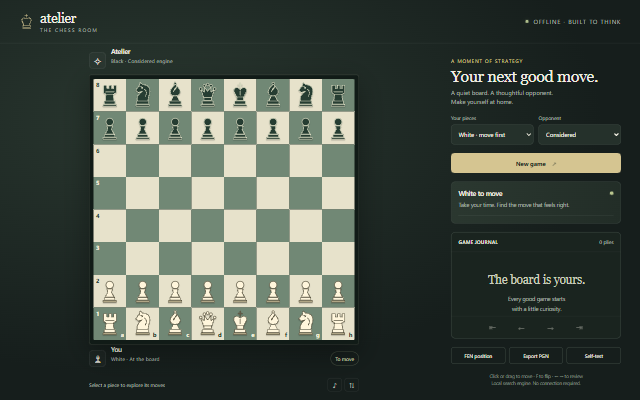
Score 94/100
Compact yet functionally complete implementation with full rules, worker engine and perft self-test. Engine is simpler and slower, without a transposition table.
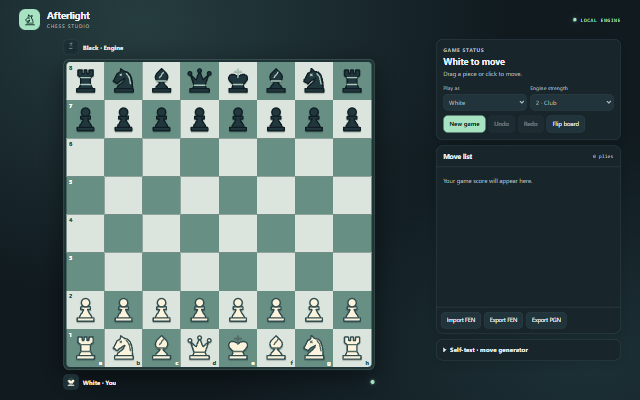
Score 99/100
A complete chess app with exact rules (perft 6/6) including FIDE draws, a strong engine in a Web Worker and complete tools.
The prompt and context
- GPT-6.1 Sol model profile (OpenAI)
- GPT-6.2 Sol model profile (OpenAI)
- Model leaderboard · Methodology
More two-model comparisons
- GPT-6 Astra vs. Claude Haiku 5.5
- Claude Opus 5.5 vs. Claude Fable 5.2
- Claude Opus 5.5 vs. GPT-6 Astra
- DeepSeek V4.1 Flash 0910 vs. DeepSeek V4.1 Flash 1017
- Kimi K3 vs. Kimi K3.1 Pro
- Grok 4.6 vs. Grok 4.7
- GPT-5.6 Terra vs. GPT-6.1 Terra
- Mistral Large 4 Preview vs. Mistral Large 4 1029
- GPT-6 Astra vs. GPT-6.2 Astra