Claude Opus 5.5 vs. Claude Fable 5.2
Claude Opus 5.5 and Claude Fable 5.2 received the same 5 zero-shot prompts – one attempt each, outputs unedited. How they did on function, looks, cost and time.
Short answer
- In our test Claude Opus 5.5 had the better result in 1 and Claude Fable 5.2 in 2 of 5 prompts, 2 tied.
- Ran on the first attempt: Claude Opus 5.5 4/5, Claude Fable 5.2 5/5.
- Average score: Claude Opus 5.5 77/100, Claude Fable 5.2 96/100 (a broken output = 0).
- Cost of all prompts: Claude Opus 5.5 ≈ $17.86, Claude Fable 5.2 ≈ $30.43 – Claude Fable 5.2 is 1.7× more expensive.
- Total generation time: Claude Opus 5.5 192 min 44 s, Claude Fable 5.2 85 min 38 s.
Tested 12 Oct 2026 – 13 Nov 2026, one attempt per prompt and model; the table shows the original outputs (a fixed copy is listed separately). This is the result of our test, not a general measure of the models' reliability. Time = from sending the prompt to the last token of the answer, thinking included (for runs in Claude Code the whole task incl. writing the file), fixes excluded. Cost = tokens × the public API price list as of the date at the model, fixes excluded; ≈ = an estimate when only the token total is known. It is not the amount actually paid – subscriptions, caching or discounts change it.
Editor's note
Both Anthropic models met the prompt requirements in full, 8/8, wherever the output ran. The whole gap in the average score (96 versus 77) comes from the New York map, which did not run for Opus 5.5 on the first attempt (its fixed copy also scores 8/8). On the other four prompts the scores are almost equal: solar system 93 versus 92, the game 97 and the monitor test 96 tied, chess 98 versus 99. Fable 5.2 generated faster (about 86 versus 193 minutes in total) but would cost more at API prices (an estimated $30 versus $18; both ran in Claude Code, so the cost is an estimate). Because of technical saving problems and the subscription limit, Fable 5.2 needed more runs – the details are in the notes on each output.
Results per prompt
| Prompt | Claude Opus 5.5 | Claude Fable 5.2 | Better result | Cost A / B | Time A / B |
|---|---|---|---|---|---|
| Solar System | 8/8 Score 93/100 | 8/8 Score 92/100 | Claude Opus 5.5 | ≈ $2.93 ≈ $7.34 | 38 min 28 s 22 min 45 s |
| GTA-style game | 8/8 Score 97/100 | 8/8 Score 97/100 | tie | ≈ $3.95 ≈ $7.14 | 67 min 54 s 21 min 08 s |
| Monitor test | 8/8 Score 96/100 | 8/8 Score 96/100 | tie | ≈ $2.65 ≈ $4.10 | 14 min 00 s 8 min 37 s |
| New York & Central Park map | broken original = 0 points fixed copy: 8/8 | 8/8 Score 96/100 | Claude Fable 5.2 | ≈ $4.33 ≈ $7.24 | 49 min 23 s 22 min 35 s |
| Chess with an engine | 8/8 Score 98/100 | 8/8 Score 99/100 | Claude Fable 5.2 | ≈ $4.00 ≈ $4.61 | 22 min 59 s 10 min 33 s |
Better result = higher overall score of the original output (60 % requirements, 30 % UX / UI, 10 % technical health). Cost by the API price list as of the date at the model, ≈ = estimate. Time = from sending the prompt to the last token of the answer, thinking included (for runs in Claude Code the whole task incl. writing the file), fixes excluded. Cost = tokens × the public API price list as of the date at the model, fixes excluded; ≈ = an estimate when only the token total is known. It is not the amount actually paid – subscriptions, caching or discounts change it.
Previews and reviewers' verdicts
Output previews – click to open them live. The text under a preview is the summary of the published review.
Solar System
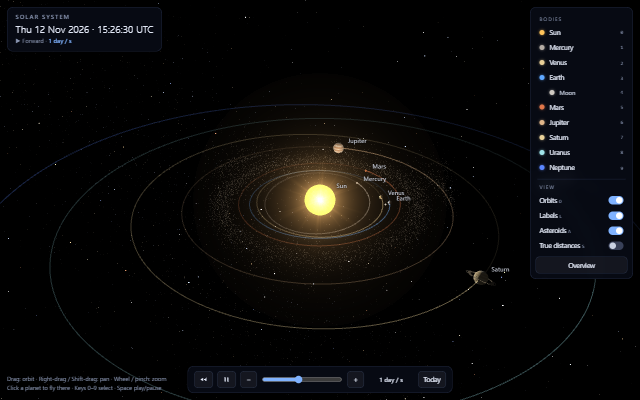
Score 93/100
Excellent, complete 3D orrery with real JPL data, rich procedural textures and polished controls. All requirements are met.
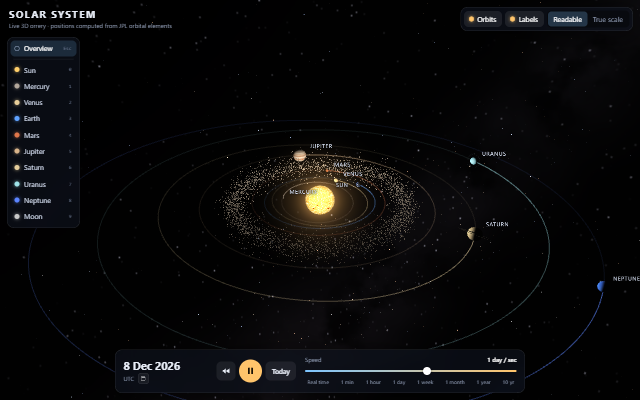
Score 92/100
An accurate, richly made orrery: JPL-element orbits, a lunar theory, detailed procedural textures with Saturn and Uranus rings, a GPU-computed asteroid belt and an animated switch to true scale.
GTA-style game
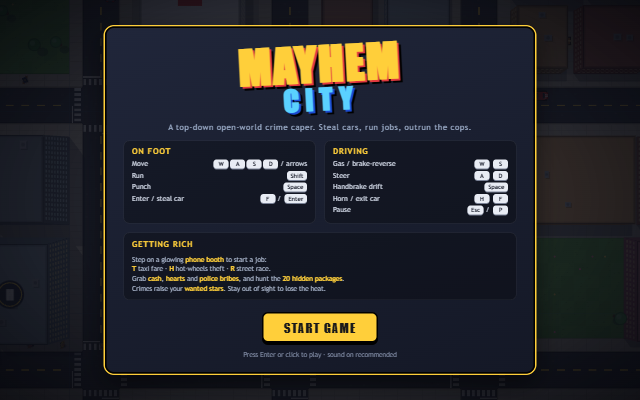
Score 97/100
Exceptionally complete top-down GTA clone with every requested system wired up. The start screen renders correctly over the generated city.
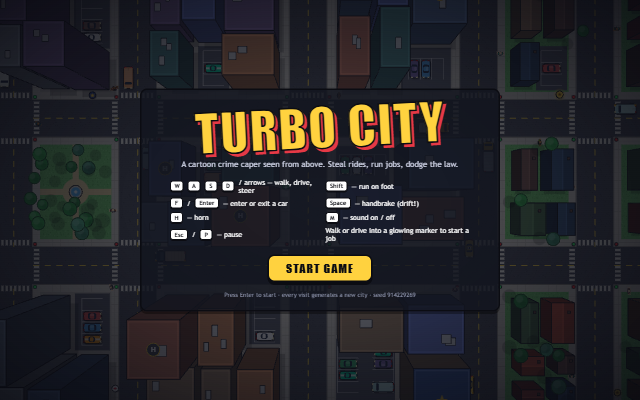
Score 97/100
The most complete GTA in the test: a living city with traffic lights and lane traffic, handbrake drift, damage and explosions, police with officers on foot and three mission types – all working while driving too.
Monitor test

Score 96/100
Professional-grade monitor test suite with pixel-exact rendering and thorough explanations. All requirements are met.
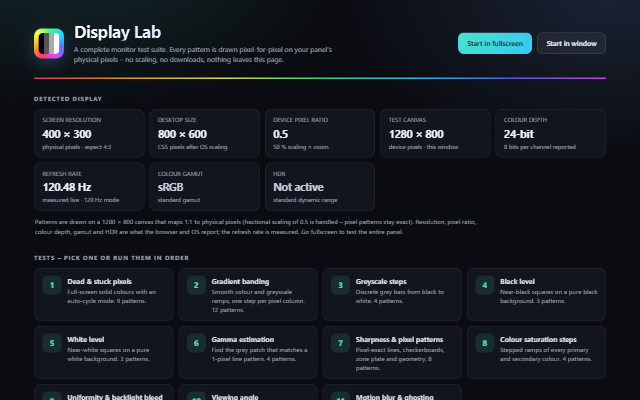
Score 96/100
An exceptionally thorough suite of 11 tests with many variants, exact physical-pixel rendering and detailed good/bad explanations. Keyboard, mouse and touch control.
New York & Central Park map
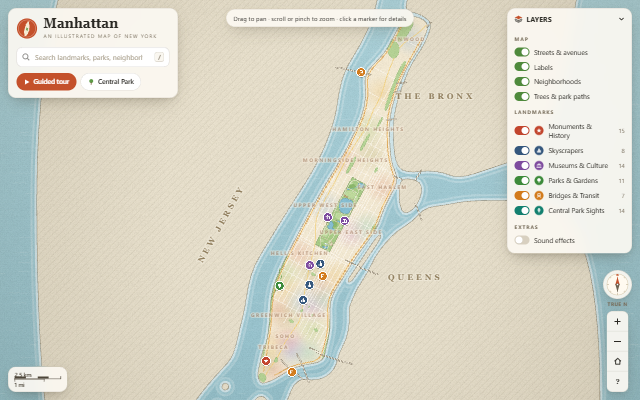
fixed copy: 8/8
The original output did not run and counts as 0 points. The preview and verdict below belong to a fixed copy by the same model (8/8) – it does not count in the comparison.
Verdict of the fixed copy: Very rich, accurate illustrated Manhattan map with a detailed Central Park and polished interaction. Every checklist item is met.
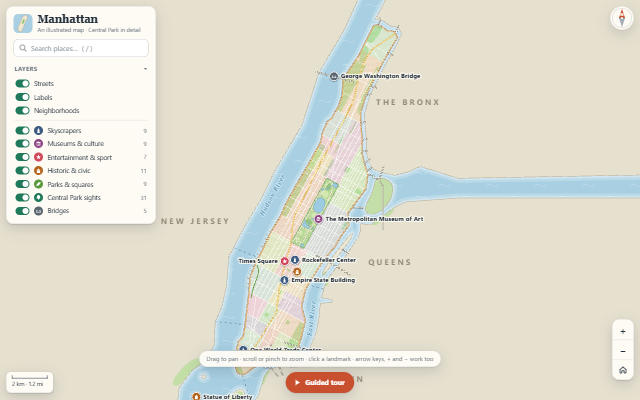
Score 96/100
The most accurate map in the test: shape, rivers, grid and places from real coordinates, a detailed Central Park, seven icon categories, cards, search and a tour.
Chess with an engine
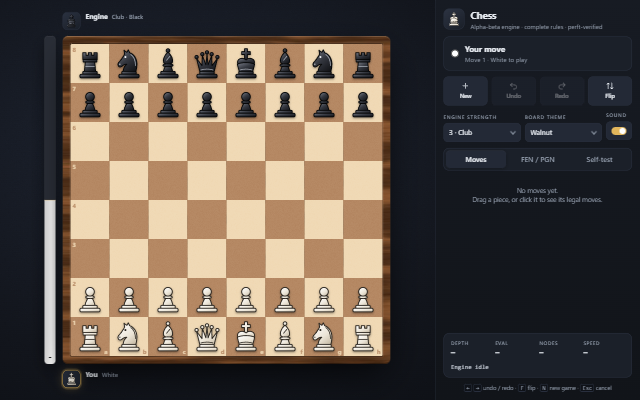
Score 98/100
Very complete, polished implementation with full rules, a strong worker-based engine and verifiable perft. No significant gaps found.
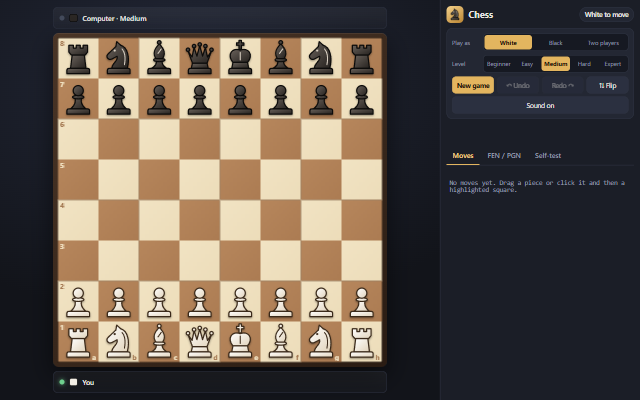
Score 99/100
An exemplary chess app: exact rules (perft 6/6), a strong engine with a transposition table in a Web Worker, five levels, complete tools and an elegant board with a material indicator.
The prompt and context
- Claude Opus 5.5 model profile (Anthropic)
- Claude Fable 5.2 model profile (Anthropic)
- Model leaderboard · Methodology
More two-model comparisons
- GPT-6 Astra vs. Claude Haiku 5.5
- Claude Opus 5.5 vs. GPT-6 Astra
- DeepSeek V4.1 Flash 0910 vs. DeepSeek V4.1 Flash 1017
- Kimi K3 vs. Kimi K3.1 Pro
- Grok 4.6 vs. Grok 4.7
- GPT-5.6 Terra vs. GPT-6.1 Terra
- Mistral Large 4 Preview vs. Mistral Large 4 1029
- GPT-6 Astra vs. GPT-6.2 Astra
- GPT-6.1 Sol vs. GPT-6.2 Sol