Which AI model built the best 3D solar system? Results of our test
Results of the same prompt side by side. Nothing runs on this page – click a row to open the output. Sort by clicking a column header; the best value is highlighted.
Short answer
- Best result in our test: GPT-6.1 Sol – 8/8 requirements, overall score 94/100, cost $0.21, time 4 min 53 s.
- Cheapest result without a critical flaw (at least 6/8, no requirement failed outright): DeepSeek V4.1 Flash 0910 – 7/8 for $0.047.
- 26 of 40 outputs ran on the first attempt (65 %).
- Looks are not function: Gemini 3.5 Flash-Lite has a look rated 70/100 but met only 3.5/8 requirements.
Tested 14 Oct 2026 – 6 Nov 2026, one attempt for each of the 40 outputs, model versions are in the table. This is the result of our test, not a general measure of a model's reliability – another attempt may turn out differently. Time = from sending the prompt to the last token of the answer, thinking included (for runs in Claude Code the whole task incl. writing the file), fixes excluded. Cost = tokens × the public API price list as of the date at the model, fixes excluded; ≈ = an estimate when only the token total is known. It is not the amount actually paid – subscriptions, caching or discounts change it.
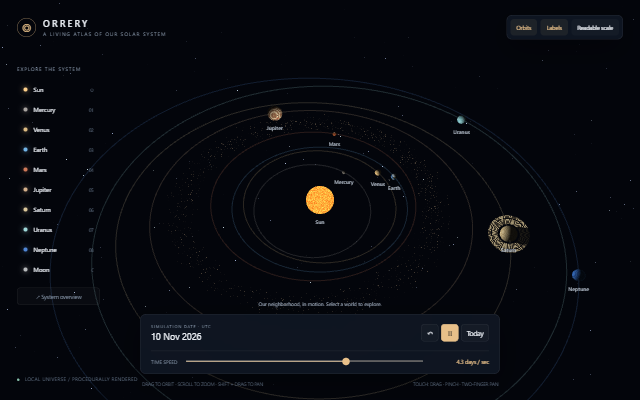 GPT-6.1 Sol medium OpenAI Model profile → | loads | 94 | 8/8 | 100 | 81 / 80 | 4 min 53 s | 138,349 | $0.21 prices as of 15/10/2026 | 31 kB 98 lines |
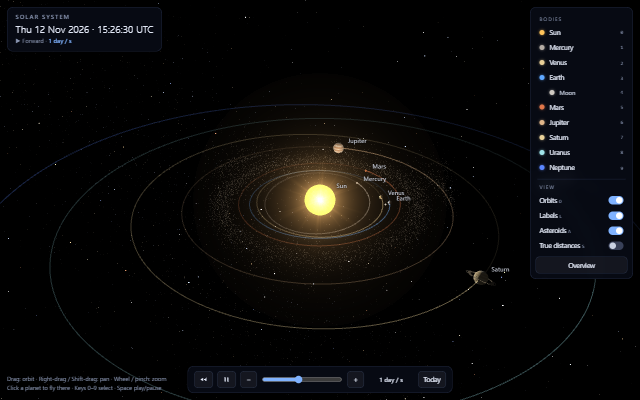 Claude Opus 5.5 medium Anthropic Model profile → | loads | 93 | 8/8 | 94 | 89 / 70 | 38 min 28 s | 159,363 | ≈ $2.93 prices as of 06/10/2026 | 67 kB 1,210 lines |
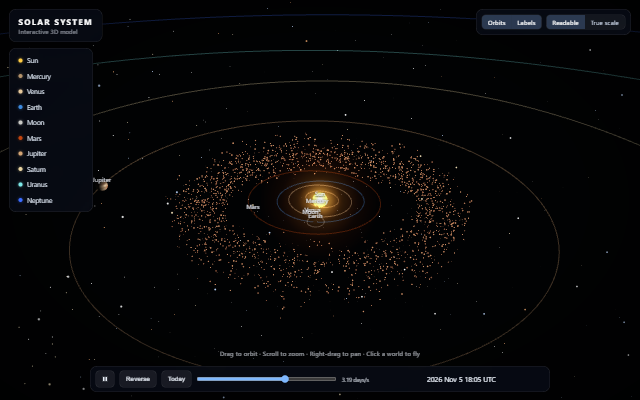 Grok 4.6 default xAI Model profile → | loads | 93 | 8/8 | 97 | 94 / 60 | 16 min 01 s | 56,405 | $0.33 prices as of 18/10/2026 | 50 kB 1,089 lines |
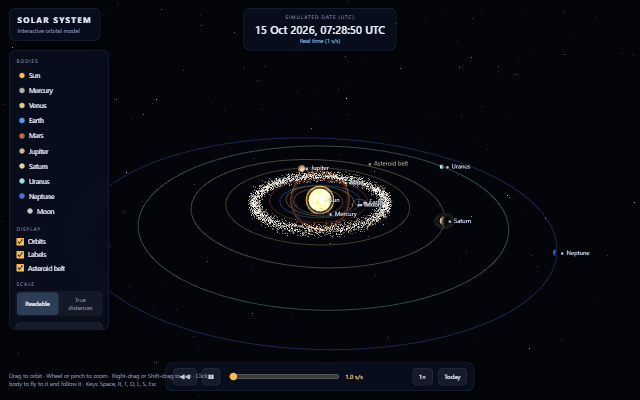 Claude Haiku 5.5 medium Anthropic Model profile → | loads | 92 | 8/8 | 94 | 91 / 60 | 11 min 27 s | 222,948 | ≈ $0.10 prices as of 06/10/2026 | 49 kB 1,268 lines |
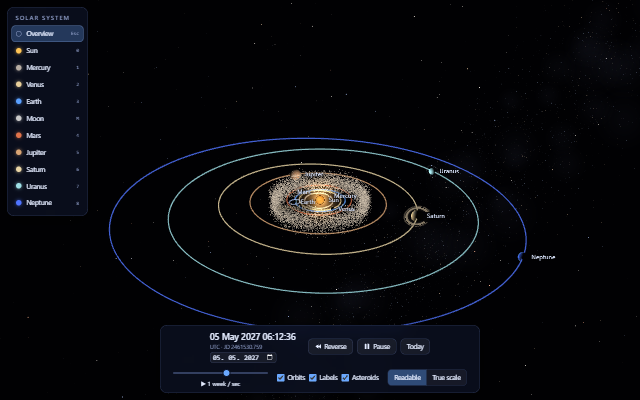 Claude Sonnet 5.5 medium Anthropic Model profile → | loads | 91 | 8/8 | 96 | 84 / 60 | 15 min 14 s | 185,039 | ≈ $1.70 prices as of 06/10/2026 | 68 kB 1,189 lines |
 GPT-6 Astra medium OpenAI Model profile → | loads | 90 | 8/8 | 100 | 76 / 60 | 4 min 25 s | 161,311 | $1.04 prices as of 15/10/2026 | 26 kB 50 lines |
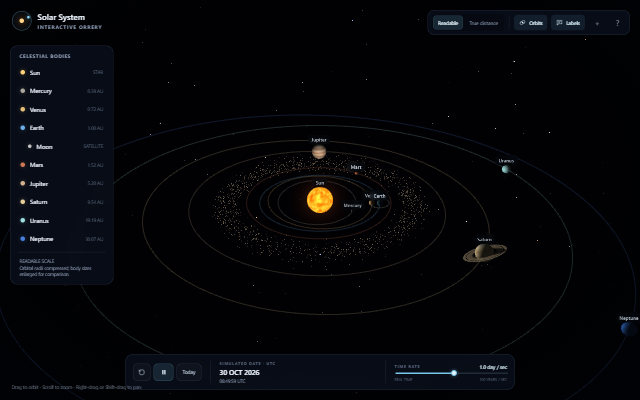 Kimi K3.1 Pro thinking Moonshot AI Model profile → | loads | 89 | 8/8 | 95 | 68 / 60 | 28 min 42 s | 64,268 | $0.64 prices as of 25/10/2026 | 73 kB 1,165 lines |
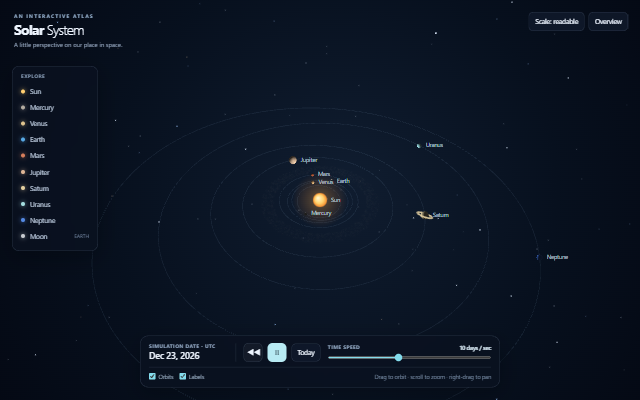 GPT-6.1 Terra medium OpenAI Model profile → | loads | 87 | 7.5/8 | 100 | 78 / 60 | 2 min 10 s | 11,954 | $0.058 prices as of 26/10/2026 | 28 kB 207 lines |
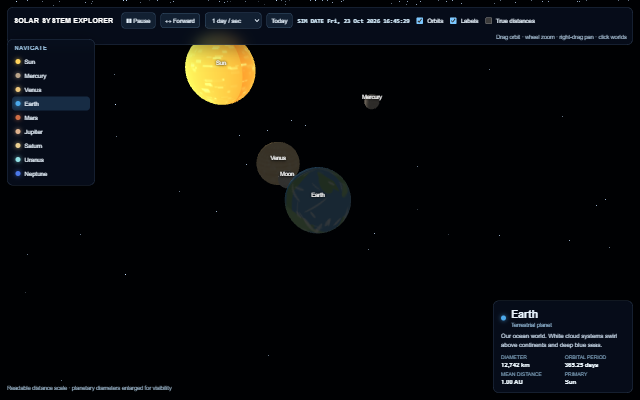 GPT-5.6 Terra medium OpenAI Model profile → | loads | 84 | 7/8 | 98 | 87 / 60 | 1 min 19 s | 10,517 | $0.12 prices as of 17/10/2026 | 25 kB 326 lines |
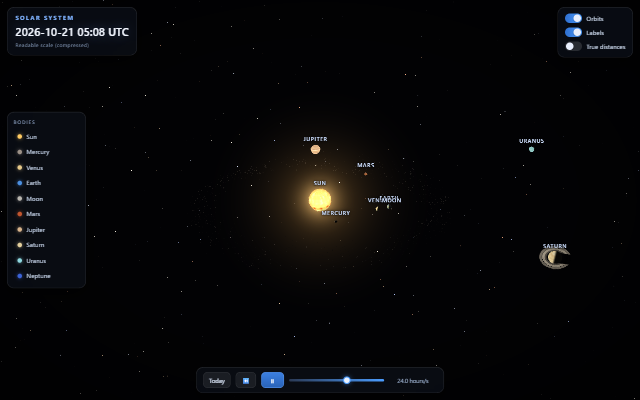 DeepSeek V4.1 Flash 0910 high DeepSeek Model profile → | loads | 84 | 7/8 | 92 | 81 / 70 | 5 min 45 s | 78,728 | $0.047 prices as of 16/10/2026 | 75 kB 2,089 lines |
 GPT-6 Sol medium OpenAI Model profile → | loads | 83 | 6.5/8 | 100 | 79 / 80 | 2 min 27 s | 244,896 | $0.26 prices as of 15/10/2026 | 31 kB 83 lines |
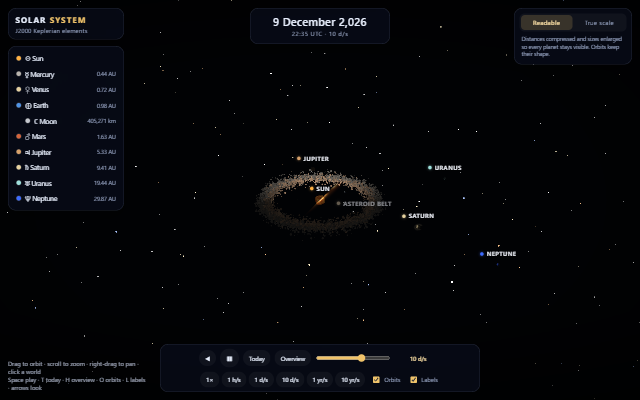 Grok 4.7 default xAI Model profile → | loads | 83 | 7/8 | 95 | 83 / 60 | 28 min 27 s | 145,007 | $0.86 prices as of 24/10/2026 | 99 kB 2,464 lines |
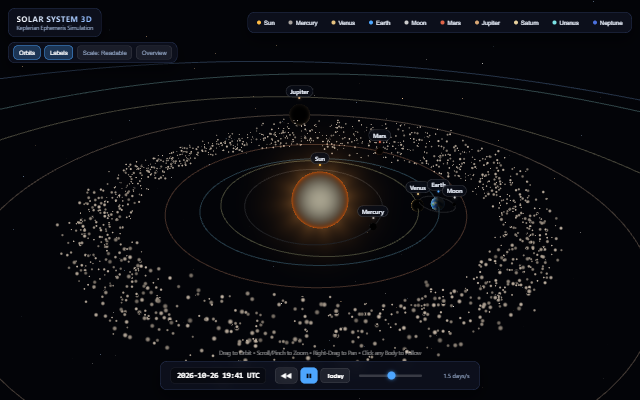 Gemini 4 Argon medium Google Model profile → | loads | 82 | 7/8 | 78 | 84 / 60 | 4 min 23 s | 29,944 | $0.30 prices as of 17/10/2026 | 72 kB 1,979 lines |
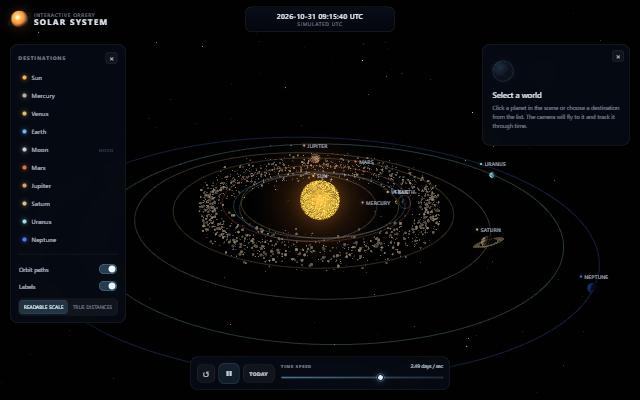 DeepSeek V4.1 Flash 1017 high DeepSeek Model profile → | loads | 82 | 7/8 | 94 | 75 / 60 | 8 min 09 s | 121,423 | $0.073 prices as of 20/10/2026 | 91 kB 2,655 lines |
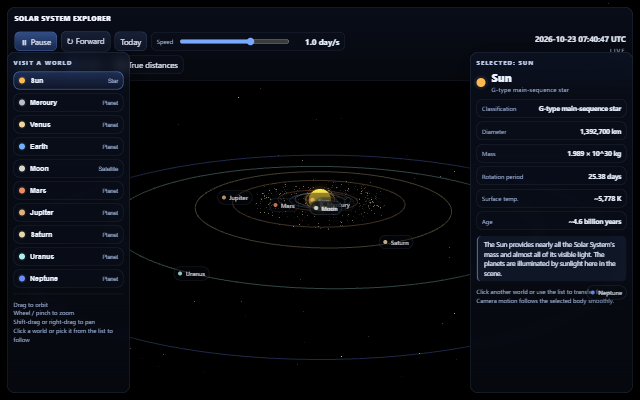 GPT-5.4 mini medium OpenAI Model profile → | loads | 80 | 6.5/8 | 98 | 92 / 50 | 5 min 46 s | 92,216 | $0.41 prices as of 17/10/2026 | 67 kB 2,097 lines |
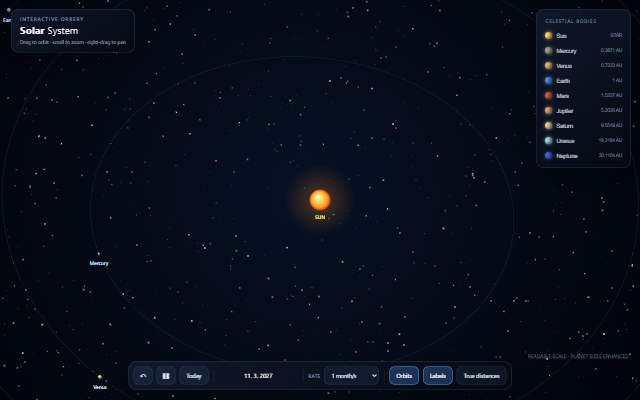 GPT-5.6 Sol medium OpenAI Model profile → | loads | 76 | 6/8 | 97 | 80 / 60 | 2 min 05 s | 223,637 | $0.33 prices as of 15/10/2026 | 19 kB 74 lines |
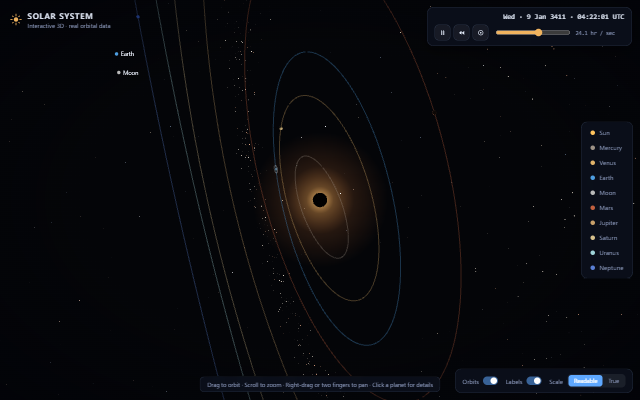 Mistral Large 4 Preview none Mistral Model profile → | loads | 75 | 6.5/8 | 96 | 80 / 30 | 46 min 26 s | 120,476 | $0.25 prices as of 17/10/2026 | 72 kB 1,678 lines |
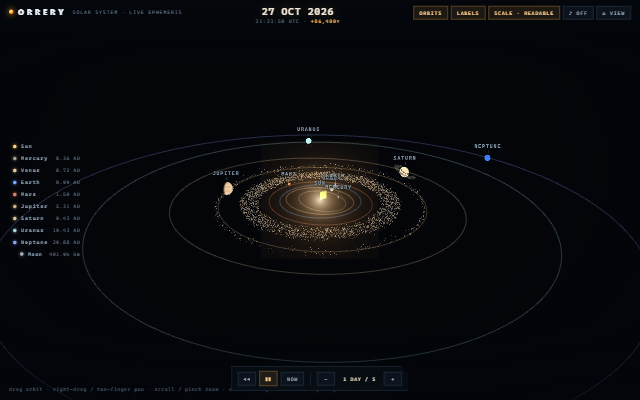 Qwen3.8 Max thinking Alibaba Model profile → | loads | 74 | 6/8 | 94 | 79 / 50 | 24 min 32 s | 65,857 | $0.39 prices as of 22/10/2026 | 68 kB 1,222 lines |
 Hy4 preview thinking Tencent Model profile → | loads | 74 | 6/8 | 96 | 78 / 50 | 9 min 10 s | 47,518 | $0.12 prices as of 06/11/2026 | 37 kB 671 lines |
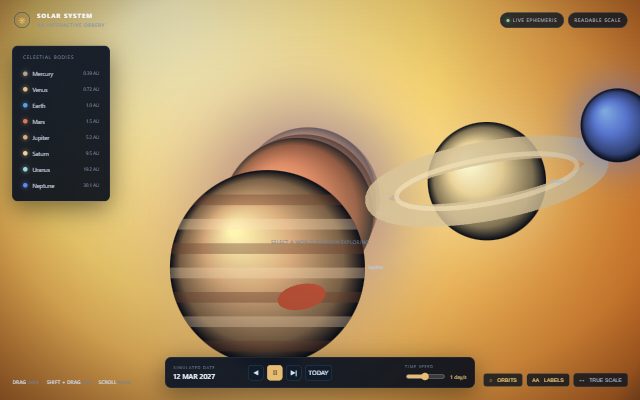 GPT-6 Luna medium OpenAI Model profile → | loads | 69 | 5.5/8 | 96 | 74 / 50 | 1 min 12 s | 224,739 | $0.00811 prices as of 15/10/2026 | 21 kB 57 lines |
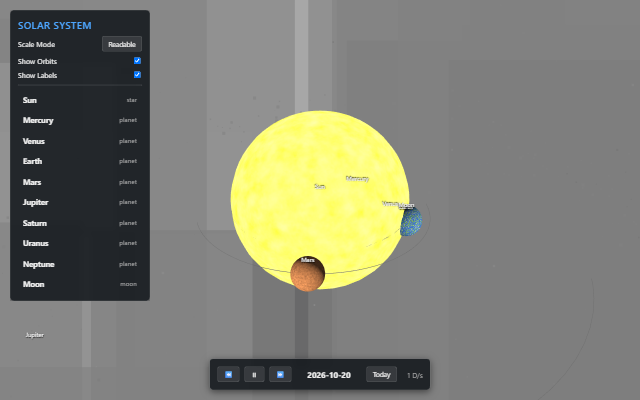 Gemini 3.1 Pro medium Google Model profile → | loads | 65 | 5/8 | 83 | 76 / 50 | 1 min 55 s | 19,706 | $0.23 prices as of 17/10/2026 | 39 kB 913 lines |
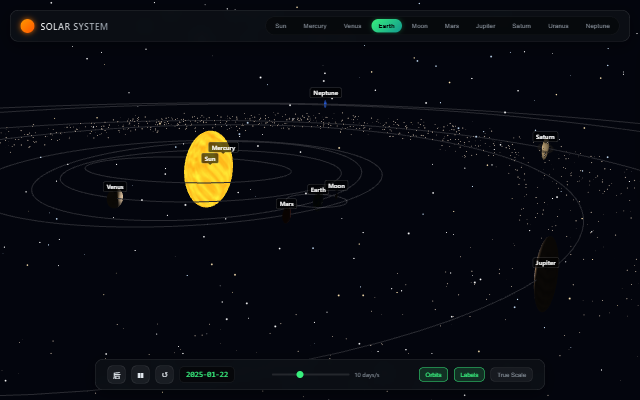 Gemini 3.6 Flash medium Google Model profile → | loads | 64 | 5/8 | 81 | 85 / 40 | 2 min 18 s | 29,794 | $0.11 prices as of 17/10/2026 | 57 kB 1,648 lines |
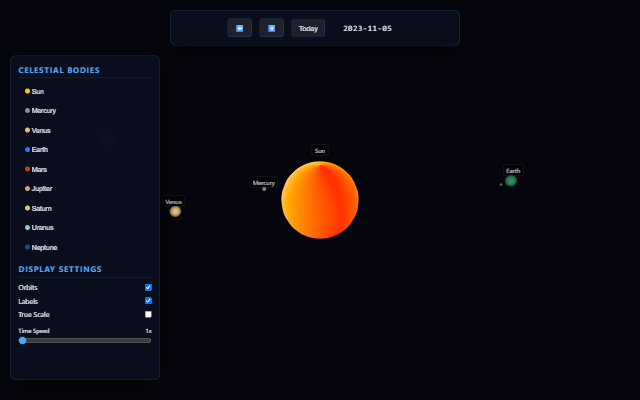 Gemini 3.5 Flash-Lite medium Google Model profile → | loads | 60 | 3.5/8 | 98 | 87 / 70 | 54 s | 17,496 | $0.043 prices as of 17/10/2026 | 49 kB 1,199 lines |
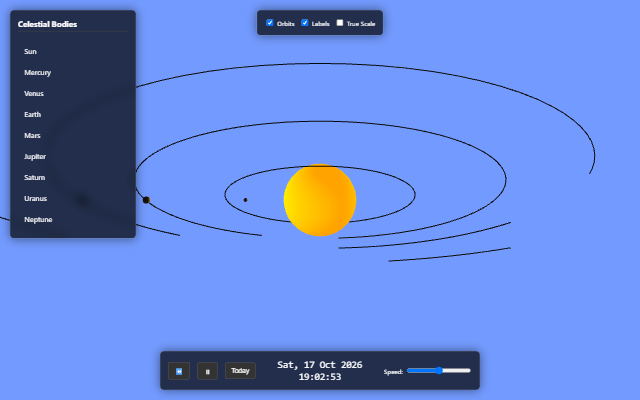 Gemma 4 31B default Google Model profile → | loads | 55 | 4/8 | 82 | 85 / 30 | 6 min 20 s | 13,814 | $0.00 prices as of 17/10/2026 | 32 kB 712 lines |
 Mistral Medium 3.5 high Mistral Model profile → | loads | 19 | 1.5/8 | 81 | 0 / 0 | 3 min 44 s | 37,053 | $0.28 prices as of 17/10/2026 | 70 kB 1,664 lines |
 Gemini 3.1 Flash-Lite medium Google Model profile → | loads | 12 | 0.5/8 | 85 | 0 / 0 | 8 s | 3,086 | $0.00413 prices as of 17/10/2026 | 6 kB 161 lines |
 GPT-5.6 Luna medium OpenAI Model profile → | broken fixed version → | 0 after fix 7 | 0/8 after fix 0/8 | 68 after fix 68 | 0 / 0 after fix 0 / 0 | 43 s | 6,043 | $0.00687 prices as of 17/10/2026 | 14 kB 67 lines |
 GPT-5.5 medium OpenAI Model profile → | broken fixed version → | 0 after fix 81 | 0/8 after fix 6.5/8 | 67 after fix 96 | 0 / 0 after fix 91 / 60 | 2 min 12 s | 12,944 | $0.38 prices as of 17/10/2026 | 29 kB 357 lines |
 Gemini 3.8 Flash medium Google Model profile → | broken fixed version → | 0 after fix 27 | 0/8 after fix 1.5/8 | 69 after fix 65 | 0 / 0 after fix 0 / 60 | – | 32,202 | $0.12 prices as of 16/10/2026 | 73 kB 2,288 lines |
 DeepSeek V4 Pro high DeepSeek Model profile → | broken fixed version → | 0 after fix 43 | 0/8 after fix 2.5/8 | 69 after fix 98 | 0 / 0 after fix 94 / 0 | 4 min 22 s | 41,688 | $0.082 prices as of 16/10/2026 | 88 kB 2,060 lines |
 Mistral Small 4 high Mistral Model profile → | broken fixed version → | 0 after fix 18 | 0/8 after fix 1.5/8 | 64 after fix 64 | 0 / 0 after fix 0 / 0 | 2 min 15 s | 27,061 | $0.016 prices as of 17/10/2026 | 42 kB 1,156 lines |
 Codestral 25.08 default Mistral Model profile → | broken fixed version → | 0 after fix 7 | 0/8 after fix 0/8 | 67 after fix 67 | 0 / 0 after fix 0 / 0 | 2 min 58 s | 21,146 | $0.019 prices as of 17/10/2026 | 90 kB 2,133 lines |
 GLM 5.3 high Z.ai Model profile → | broken fixed version → | 0 after fix 26 | 0/8 after fix 2.5/8 | 70 after fix 71 | 0 / 0 after fix 0 / 0 | 6 min 34 s | 101,405 | $0.45 prices as of 17/10/2026 | 57 kB 1,215 lines |
 Kimi K3 thinking Moonshot AI Model profile → | broken fixed version → | 0 after fix 92 | 0/8 after fix 8/8 | 66 after fix 95 | 0 / 0 after fix 91 / 60 | 37 min 14 s | 64,889 | $0.97 prices as of 22/10/2026 | 55 kB 1,064 lines |
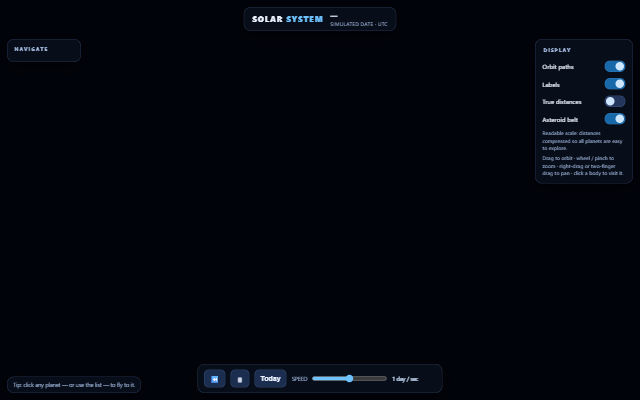 Muse Wonder thinking Meta Model profile → | broken fixed version → | 0 after fix 83 | 0/8 after fix 7/8 | – after fix 96 | – / 0 after fix 79 / 60 | 2 min 03 s | 20,212 | $0.40 prices as of 25/10/2026 | 41 kB 367 lines |
 MiniMax M3.1 Flash thinking MiniMax Model profile → | broken fixed version → | 0 after fix 81 | 0/8 after fix 7/8 | – after fix 95 | – / 0 after fix 66 / 60 | 6 min 39 s | 74,914 | $0.045 prices as of 25/10/2026 | 92 kB 2,153 lines |
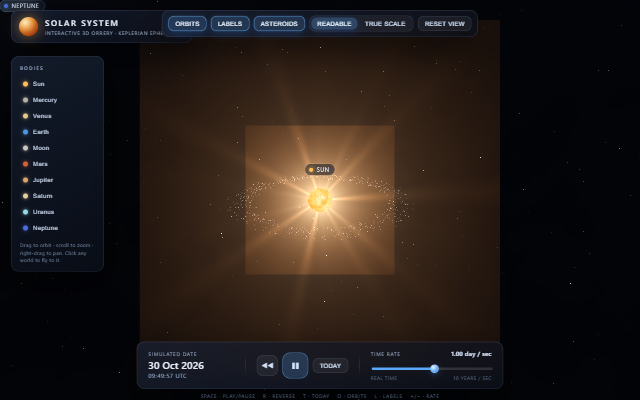 MiMo-V2.6-Pro thinking Xiaomi Model profile → | broken fixed version → | 0 after fix 76 | 0/8 after fix 6.5/8 | 94 after fix 93 | 76 / 0 after fix 79 / 40 | 23 min 30 s | 82,126 | $0.071 prices as of 25/10/2026 | 80 kB 1,941 lines |
 Qwen3.6 27B thinking Alibaba Model profile → | broken fixed version → | 0 after fix 7 | 0/8 after fix 0/8 | – after fix 68 | – / 0 after fix 0 / 0 | 4 min 47 s | 20,815 | $0.041 prices as of 25/10/2026 | 49 kB 1,328 lines |
 Mistral Large 4 1029 medium Mistral Model profile → | broken fixed version → | 0 after fix 7 | 0/8 after fix 0/8 | 68 after fix 68 | 0 / 0 after fix 0 / 0 | 2 min 15 s | 18,521 | $0.038 prices as of 31/10/2026 | 34 kB 320 lines |
 GLM-5.3-Flash high Z.ai Model profile → | broken fixed version → | 0 after fix 75 | 0/8 after fix 6/8 | 70 after fix 100 | 0 / 0 after fix 75 / 60 | 8 min 12 s | 80,922 | $0.040 prices as of 31/10/2026 | 57 kB 1,094 lines |
Cost = tokens priced with the API price list valid on the date shown next to the cost (prices change). ≈ = estimate (only the total token count is known), no ≈ = exact from input / output tokens. “Loads” = the page opens without errors; technical health also checks behaviour during use – judge the quality in the viewer.
Evaluation
40 outputs from 40 models for the same zero-shot prompt – each one the model's first answer, published unedited.
- 4/8average score
- 26/40working outputs
- 86/100avg. technical health
- 55/100avg. UX
Broken (do not run): 14, 14 of them with a copy fixed by the same model. The average checklist score is 4/8 (a broken output scores 0), 6.2/8 among working ones. Best result in our test: Claude Opus 5.5, Claude Haiku 5.5, Claude Sonnet 5.5 and 4 more – 8/8. Weakest working: Gemini 3.1 Flash-Lite – 0.5/8.
How the 8 requirements were met
From 26 working outputs: ✓ met, ½ partly, ✗ missing. Rate = (✓ + ½ × 0.5) / number of outputs.
| Requirement | ✓ | ½ | ✗ | Rate |
|---|---|---|---|---|
| 3D scene 3D scene: Sun, 8 planets, Moon, asteroid belt, stars |
17 | 8 | 1 | 81 % |
| Recognizable planets (Jupiter bands & spot, Saturn rings, Earth oceans & clouds), sunlight | 13 | 12 | 1 | 73 % |
| Real data Real data: periods, eccentricity & inclination, positions roughly right for the date |
15 | 9 | 2 | 75 % |
| Time Time: play/pause, reverse, real time to years/s, “today”, date shown |
17 | 8 | 1 | 81 % |
| Camera Camera: orbit, zoom and pan with mouse and touch |
15 | 9 | 2 | 75 % |
| Click / list Click / list: smooth fly-to, follow, info panel |
17 | 7 | 2 | 79 % |
| Orbit & label toggles, readable vs true scale switch | 13 | 11 | 2 | 71 % |
| Single file, no external assets, full window, resize & high-DPI, runs without errors | 20 | 4 | 2 | 85 % |
Strengths
The requirements the models met best – quotes from the reviewer's verdicts:
Single file, no external assets, full window, resize & high-DPI, runs without errors · 85 % met
Single file, no assets, resize and high-DPI handled, renders fine.
– Claude Opus 5.5Single self-contained file, resize and high-DPI handled.
– Claude Haiku 5.5
3D scene · 81 % met
Sun, eight planets, Moon, asteroid belt and stars all present.
– Claude Opus 5.5Sun, eight planets, Moon, asteroid belt and starfield present.
– Claude Haiku 5.5
Typical mistakes
The requirements the models most often missed or met only partly:
Orbit & label toggles, readable vs true scale switch · 71 % met
Labels missing, orbits invisible, scale switch barely works
– Mistral Medium 3.5Toggles do nothing; no scale switch.
– Gemini 3.1 Flash-Lite
Recognizable planets (Jupiter bands & spot, Saturn rings, Earth oceans & clouds), sunlight · 73 % met
No visible planets or planet details.
– Gemini 3.1 Flash-LiteGood textures and lighting, but spheres render with a hole grid.
– DeepSeek V4.1 Flash 1017
Camera · 75 % met
Camera is coded, but the frozen page does not respond.
– Mistral Medium 3.5Camera cannot be controlled.
– Gemini 3.1 Flash-Lite
Agreement of two independent reviewers
The checklist of 41 outputs was filled in independently by two AI reviewers, Claude Opus 5.5 and Codex (GPT-6 Astra, medium). They agreed on 274 of 328 items (84 %). Average score by Claude 5.1/8, by Codex 5/8. Codex gave a lower score for 19, a higher one for 8 and the same for 14 outputs. They disagreed most often on: Orbit & label toggles, readable vs true scale switch (11×), Click / list (10×), Single file, no external assets, full window, resize & high-DPI, runs without errors (7×).
Where the reviewers disagree, the stricter (lower) verdict is proposed; the published score is approved by a human.
Objective tests
Measured by a tool, not by a person or an AI – so they are shown even before the scores are approved.
- Tech: average 86/100 from 37 measurements; highest GPT-6 Astra (100), lowest Mistral Small 4 (64). Measures Lighthouse, smoothness, errors during automated use, the mobile layout and whether the controls work.
- UX / UI: average 55/100 from 37 measurements; highest Grok 4.6 (94), lowest GLM-5.3-Flash (0). Measures control size, layout at 3 widths, keyboard, feedback and readability.