Which AI model drew the best map of New York? Results of our test
Results of the same prompt side by side. Nothing runs on this page – click a row to open the output. Sort by clicking a column header; the best value is highlighted.
Short answer
- Best result in our test: Grok 4.7 – 8/8 requirements, overall score 95/100, cost $1.45, time 51 min 52 s.
- Cheapest result without a critical flaw (at least 6/8, no requirement failed outright): GLM-5.3-Flash – 6/8 for $0.054.
- 30 of 40 outputs ran on the first attempt (75 %).
Tested 14 Oct 2026 – 6 Nov 2026, one attempt for each of the 40 outputs, model versions are in the table. This is the result of our test, not a general measure of a model's reliability – another attempt may turn out differently. Time = from sending the prompt to the last token of the answer, thinking included (for runs in Claude Code the whole task incl. writing the file), fixes excluded. Cost = tokens × the public API price list as of the date at the model, fixes excluded; ≈ = an estimate when only the token total is known. It is not the amount actually paid – subscriptions, caching or discounts change it.
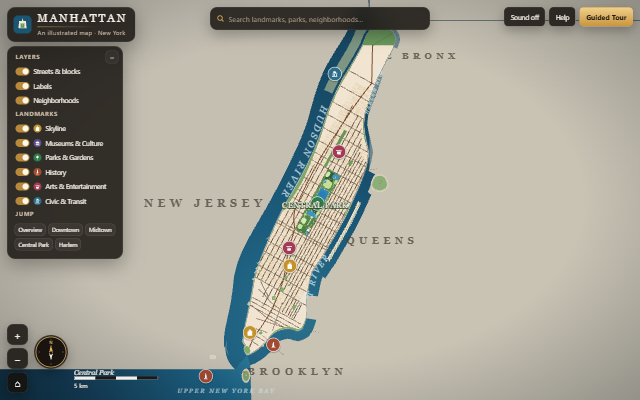 Grok 4.7 default xAI Model profile → | loads | 95 | 8/8 | 99 | 87 / 80 | 51 min 52 s | 243,331 | $1.45 prices as of 24/10/2026 | 161 kB 2,919 lines |
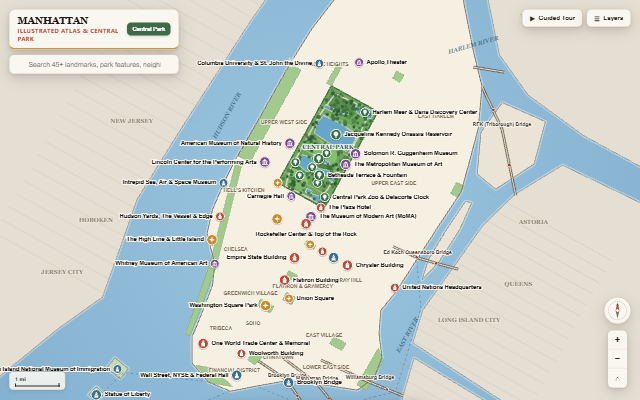 Gemini 4 Argon medium Google Model profile → | loads | 93 | 8/8 | 98 | 84 / 70 | 6 min 34 s | 40,036 | $0.40 prices as of 17/10/2026 | 103 kB 2,825 lines |
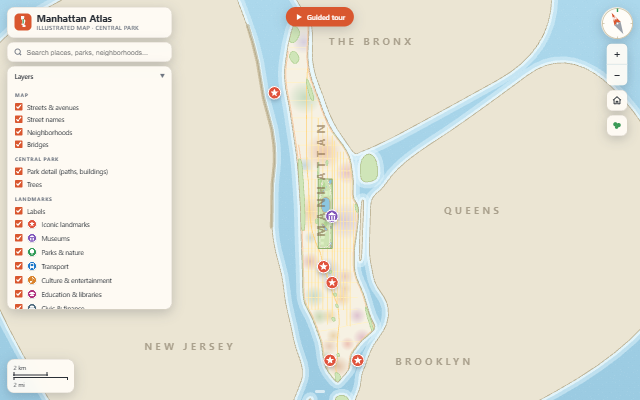 Claude Sonnet 5.5 medium Anthropic Model profile → | loads | 91 | 8/8 | 98 | 80 / 60 | 37 min 03 s | 228,876 | ≈ $2.11 prices as of 06/10/2026 | 98 kB 1,143 lines |
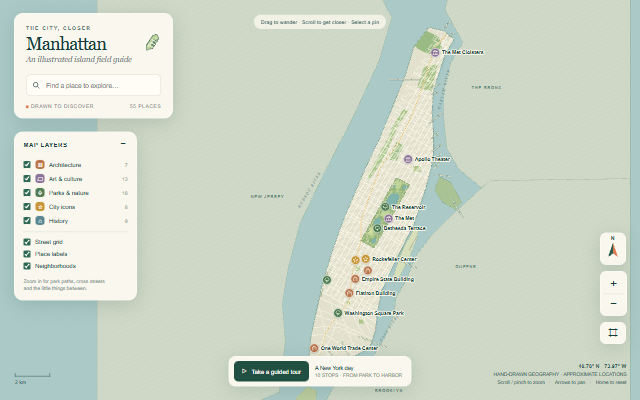 GPT-6 Astra medium OpenAI Model profile → | loads | 91 | 8/8 | 95 | 62 / 80 | 9 min 17 s | 229,263 | $1.50 prices as of 15/10/2026 | 57 kB 233 lines |
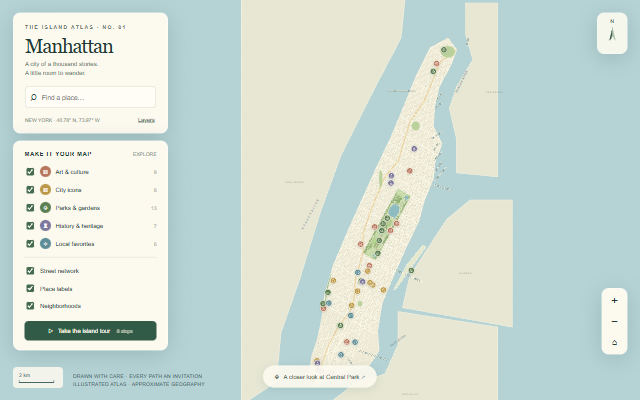 GPT-6.1 Sol medium OpenAI Model profile → | loads | 88 | 7.5/8 | 94 | 67 / 80 | 6 min 54 s | 191,285 | $0.21 prices as of 15/10/2026 | 42 kB 130 lines |
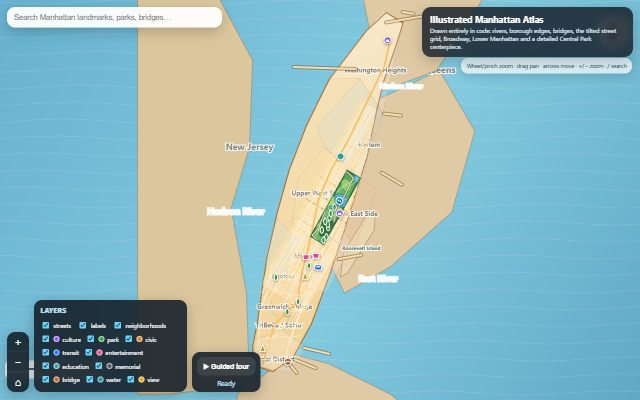 GPT-5.5 medium OpenAI Model profile → | loads | 88 | 7.5/8 | 98 | 73 / 70 | 3 min 02 s | 18,651 | $0.55 prices as of 17/10/2026 | 42 kB 699 lines |
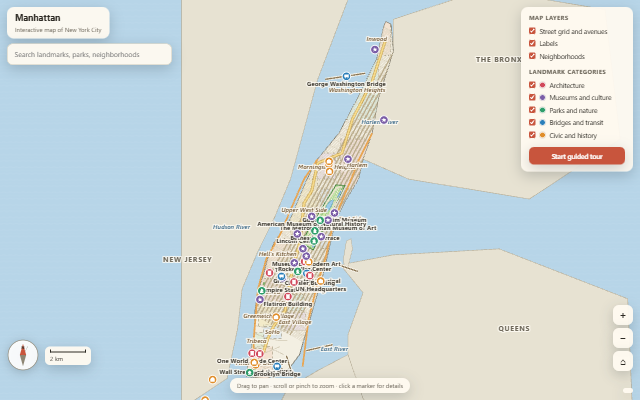 Claude Haiku 5.5 medium Anthropic Model profile → | loads | 87 | 7.5/8 | 98 | 78 / 60 | 9 min 52 s | 199,031 | ≈ $0.090 prices as of 06/10/2026 | 41 kB 653 lines |
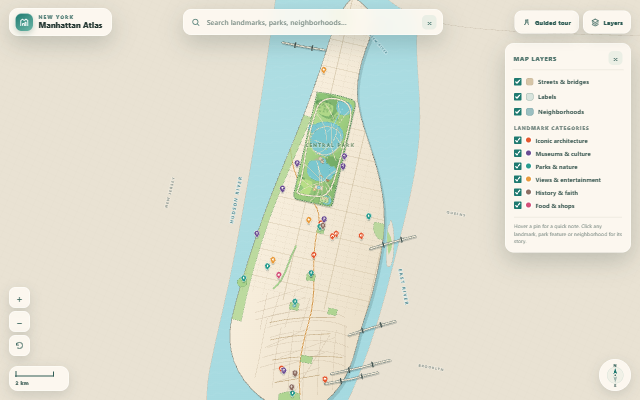 DeepSeek V4.1 Flash 1017 high DeepSeek Model profile → | loads | 83 | 7.5/8 | 98 | 35 / 80 | 9 min 30 s | 134,049 | $0.080 prices as of 20/10/2026 | 107 kB 2,490 lines |
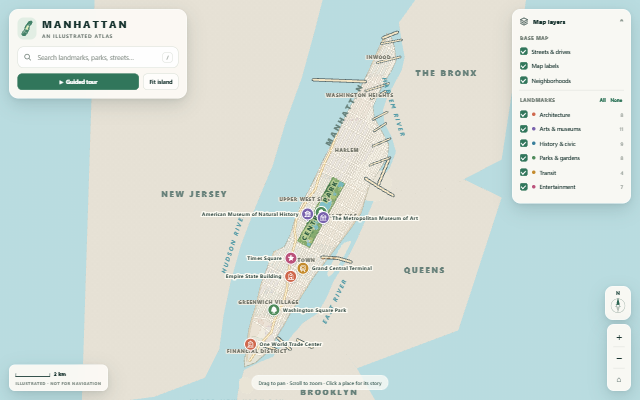 Kimi K3.1 Pro thinking Moonshot AI Model profile → | loads | 82 | 7/8 | 94 | 67 / 70 | 32 min 09 s | 74,126 | $0.74 prices as of 25/10/2026 | 101 kB 1,502 lines |
 GPT-6 Sol medium OpenAI Model profile → | loads | 80 | 6.5/8 | 100 | 70 / 70 | 3 min 13 s | 227,541 | $0.24 prices as of 15/10/2026 | 37 kB 189 lines |
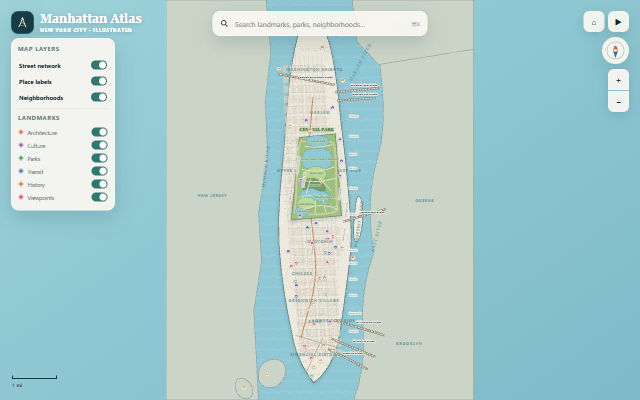 GPT-5.6 Sol medium OpenAI Model profile → | loads | 79 | 6.5/8 | 94 | 62 / 80 | 2 min 46 s | 203,462 | $0.34 prices as of 15/10/2026 | 29 kB 102 lines |
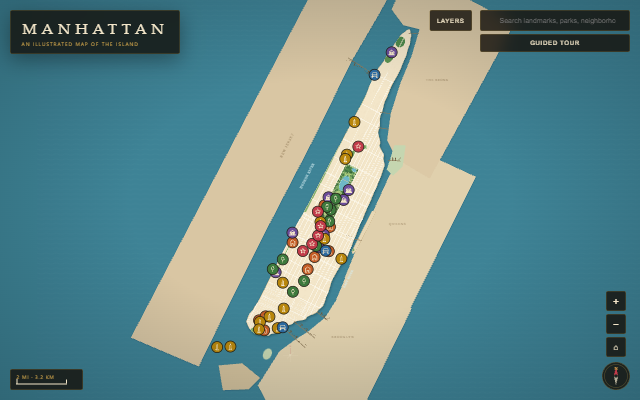 Grok 4.6 default xAI Model profile → | loads | 79 | 6.5/8 | 81 | 67 / 80 | 18 min 21 s | 72,150 | $0.43 prices as of 18/10/2026 | 76 kB 1,386 lines |
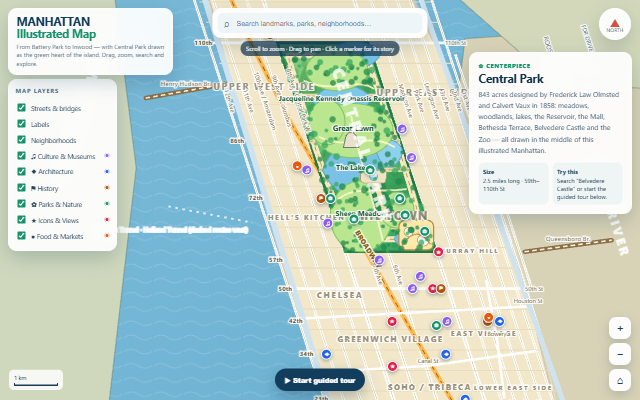 Muse Wonder thinking Meta Model profile → | loads | 79 | 6.5/8 | 94 | 67 / 70 | 2 min 13 s | 19,583 | $0.38 prices as of 25/10/2026 | 35 kB 253 lines |
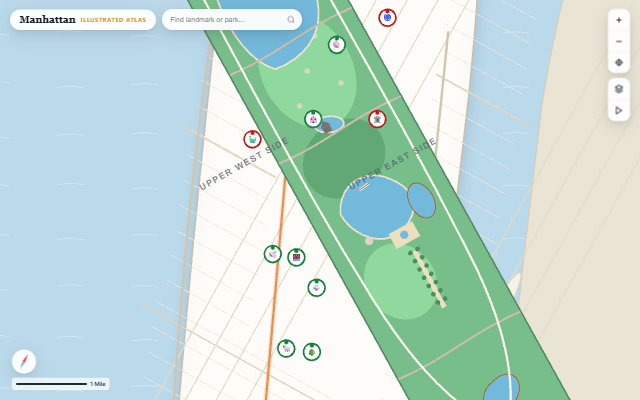 Gemini 3.8 Flash medium Google Model profile → | loads | 77 | 6.5/8 | 84 | 73 / 60 | 4 min 03 s | 31,029 | $0.12 prices as of 16/10/2026 | 67 kB 1,762 lines |
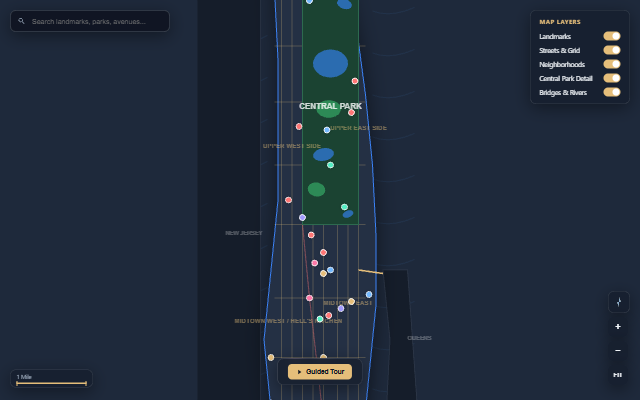 Gemini 3.6 Flash medium Google Model profile → | loads | 76 | 6/8 | 98 | 89 / 50 | 2 min 17 s | 26,897 | $0.100 prices as of 17/10/2026 | 65 kB 1,632 lines |
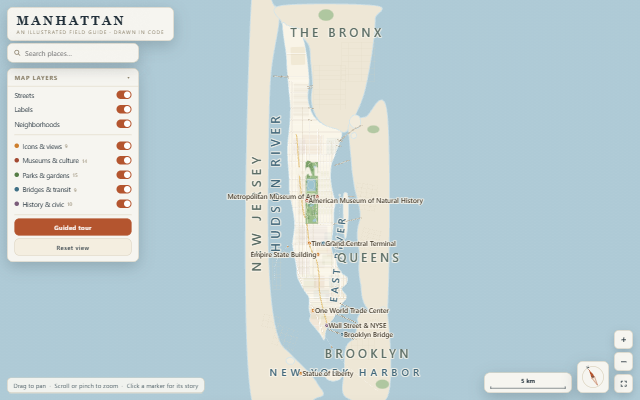 GLM-5.3-Flash high Z.ai Model profile → | loads | 76 | 6/8 | 94 | 67 / 80 | 8 min 22 s | 107,863 | $0.054 prices as of 31/10/2026 | 70 kB 1,025 lines |
 Gemini 3.1 Pro medium Google Model profile → | loads | 74 | 6/8 | 96 | 81 / 50 | 1 min 55 s | 17,987 | $0.21 prices as of 17/10/2026 | 32 kB 745 lines |
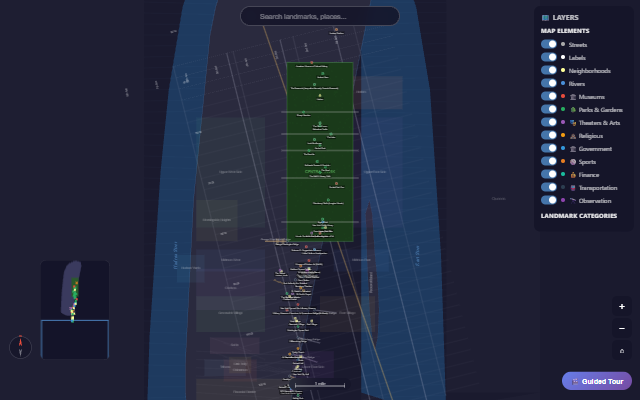 Qwen3.6 27B thinking Alibaba Model profile → | loads | 70 | 5.5/8 | 98 | 79 / 50 | 5 min 35 s | 24,889 | $0.049 prices as of 25/10/2026 | 63 kB 1,467 lines |
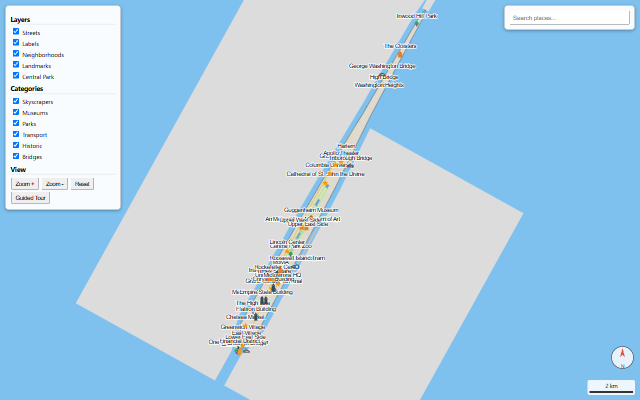 Hy4 preview thinking Tencent Model profile → | loads | 70 | 6/8 | 98 | 71 / 30 | 9 min 05 s | 40,803 | $0.10 prices as of 06/11/2026 | 26 kB 467 lines |
 GPT-5.4 mini medium OpenAI Model profile → | loads | 66 | 6/8 | 95 | 67 / 10 | 7 min 15 s | 118,367 | $0.53 prices as of 17/10/2026 | 94 kB 2,250 lines |
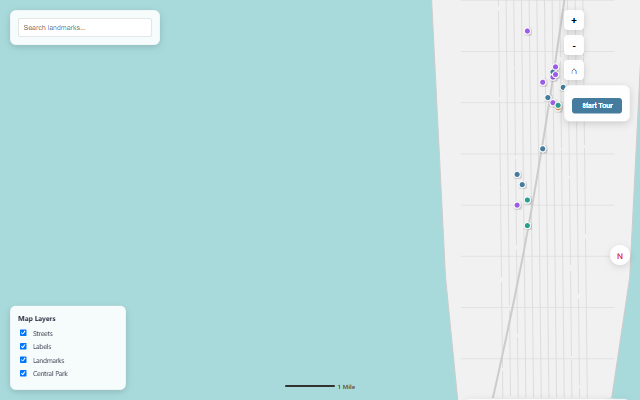 Gemma 4 31B default Google Model profile → | loads | 62 | 4.5/8 | 98 | 83 / 40 | 4 min 09 s | 9,177 | $0.00 prices as of 17/10/2026 | 23 kB 534 lines |
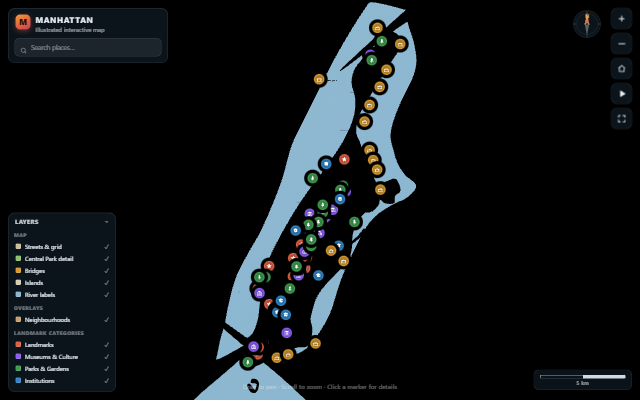 DeepSeek V4.1 Flash 0910 high DeepSeek Model profile → | loads | 61 | 4.5/8 | 98 | 87 / 30 | 6 min 57 s | 93,586 | $0.056 prices as of 16/10/2026 | 82 kB 1,701 lines |
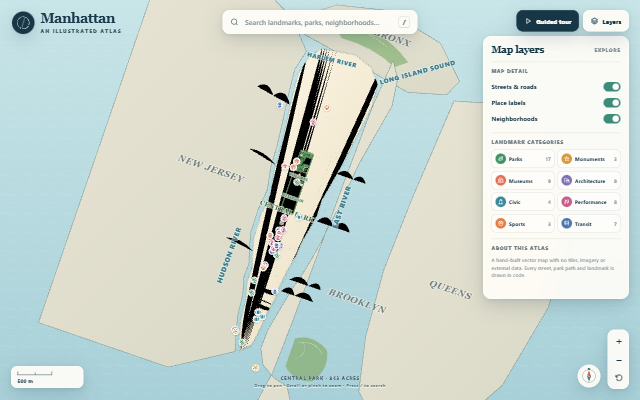 MiniMax M3.1 Flash thinking MiniMax Model profile → | loads | 59 | 4.5/8 | 93 | 59 / 50 | 7 min 34 s | 57,588 | $0.034 prices as of 25/10/2026 | 94 kB 2,057 lines |
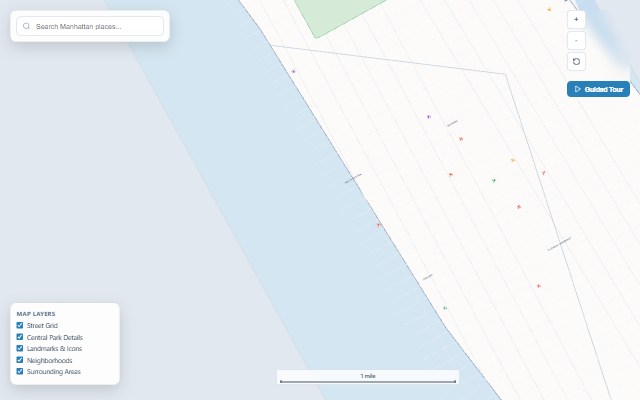 Gemini 3.5 Flash-Lite medium Google Model profile → | loads | 58 | 4.5/8 | 97 | 86 / 10 | 48 s | 16,156 | $0.039 prices as of 17/10/2026 | 47 kB 1,231 lines |
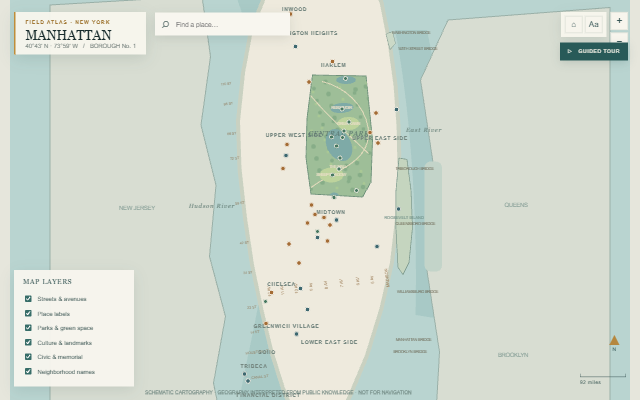 GPT-6 Luna medium OpenAI Model profile → | loads | 57 | 4/8 | 98 | 62 / 50 | 1 min 22 s | 228,992 | $0.00800 prices as of 15/10/2026 | 25 kB 65 lines |
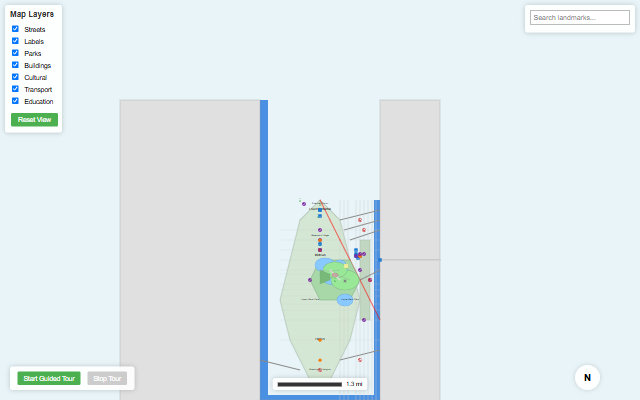 Mistral Medium 3.5 high Mistral Model profile → | loads | 51 | 4/8 | 91 | 67 / 10 | 5 min 32 s | 51,330 | $0.38 prices as of 17/10/2026 | 43 kB 1,190 lines |
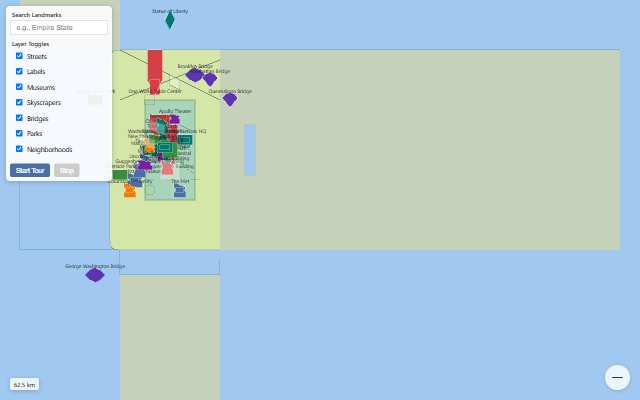 Mistral Small 4 high Mistral Model profile → | loads | 50 | 3.5/8 | 83 | 86 / 20 | 2 min 02 s | 24,465 | $0.014 prices as of 17/10/2026 | 48 kB 1,412 lines |
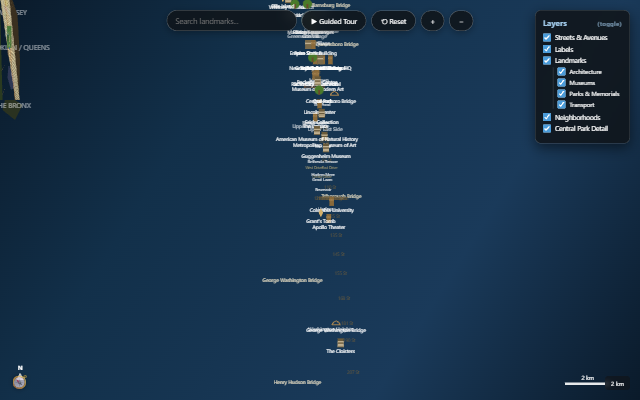 DeepSeek V4 Pro high DeepSeek Model profile → | loads | 44 | 3/8 | 82 | 76 / 10 | 3 min 24 s | 31,746 | $0.062 prices as of 16/10/2026 | 59 kB 1,566 lines |
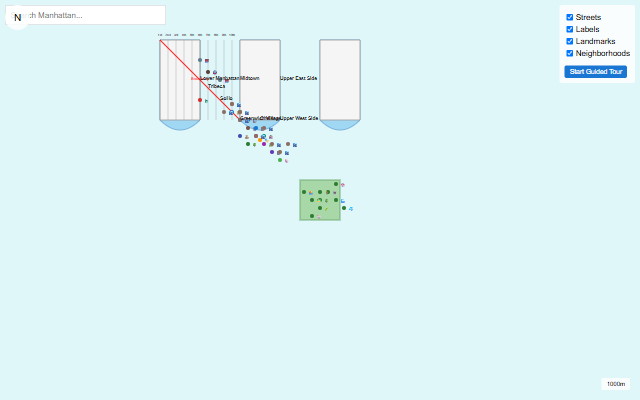 Codestral 25.08 default Mistral Model profile → | loads | 44 | 3/8 | 100 | 78 / 0 | 1 min 14 s | 8,234 | $0.00714 prices as of 17/10/2026 | 31 kB 688 lines |
 Gemini 3.1 Flash-Lite medium Google Model profile → | loads | 41 | 2.5/8 | 92 | 50 / 40 | 9 s | 3,996 | $0.00544 prices as of 17/10/2026 | 9 kB 184 lines |
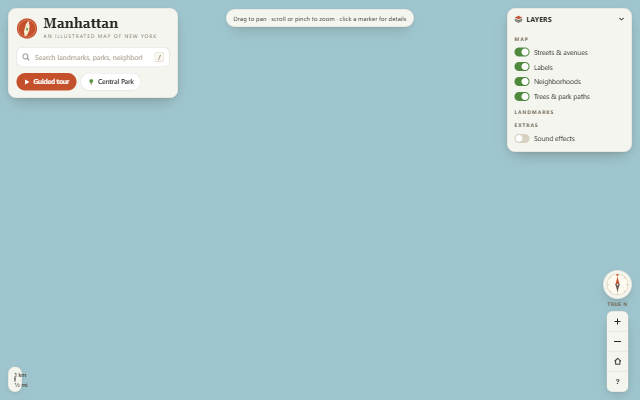 Claude Opus 5.5 medium Anthropic Model profile → | broken fixed version → | 0 after fix 95 | 0/8 after fix 8/8 | 70 after fix 99 | 0 / 0 after fix 79 / 90 | 49 min 23 s | 235,314 | ≈ $4.33 prices as of 06/10/2026 | 119 kB 1,703 lines |
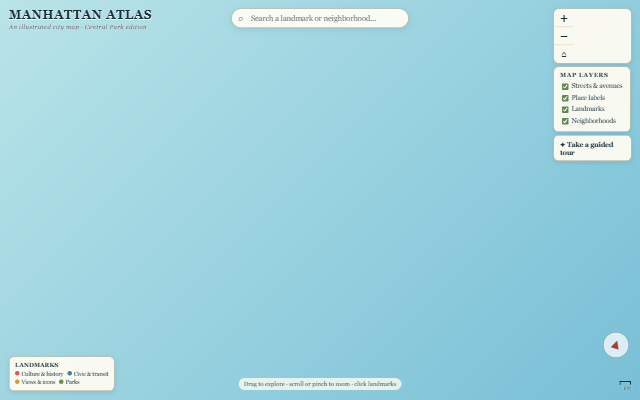 GPT-5.6 Terra medium OpenAI Model profile → | broken fixed version → | 0 after fix 71 | 0/8 after fix 5.5/8 | 71 after fix 100 | 0 / 0 after fix 69 / 60 | 1 min 26 s | 10,564 | $0.12 prices as of 17/10/2026 | 27 kB 357 lines |
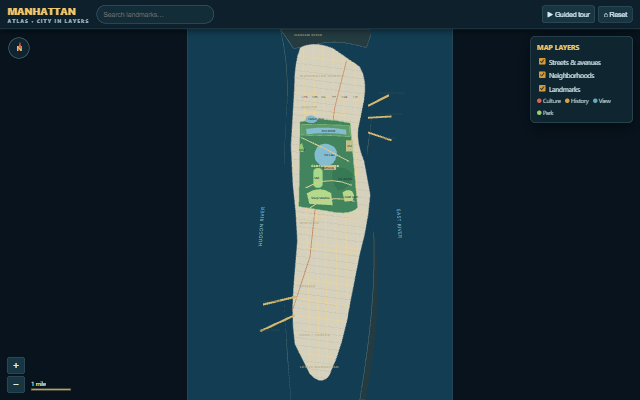 GPT-5.6 Luna medium OpenAI Model profile → | broken fixed version → | 0 after fix 67 | 0/8 after fix 5.5/8 | 55 after fix 80 | 0 / 0 after fix 67 / 50 | 48 s | 6,880 | $0.00782 prices as of 17/10/2026 | 18 kB 159 lines |
 GLM 5.3 high Z.ai Model profile → | broken | 0 | 0/8 | 83 | 0 / 0 | 9 min 56 s | 128,440 | $0.56 prices as of 17/10/2026 | 30 kB 444 lines |
|
Mistral Model profile → | broken | 0 | 0/8 | – | – / 0 | 24 min 22 s | 128,449 | $0.27 prices as of 17/10/2026 | – |
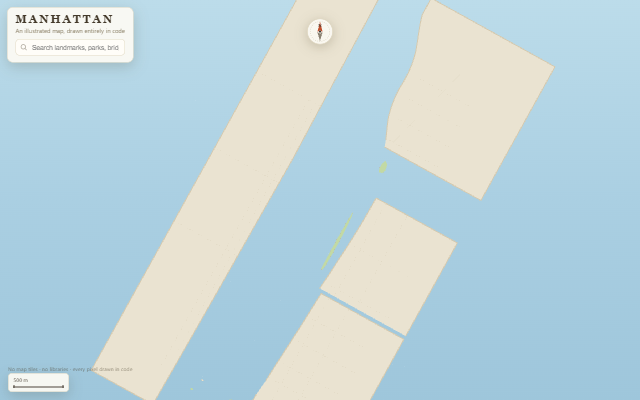 Kimi K3 thinking Moonshot AI Model profile → | broken fixed version → | 0 after fix 84 | 0/8 after fix 7/8 | 85 after fix 100 | 81 / 0 after fix 80 / 60 | 49 min 07 s | 88,683 | $1.32 prices as of 22/10/2026 | 82 kB 1,002 lines |
 Qwen3.8 Max thinking Alibaba Model profile → | broken fixed version → | 0 after fix 83 | 0/8 after fix 7/8 | 71 after fix 99 | 0 / 0 after fix 59 / 80 | 35 min 39 s | 96,890 | $0.58 prices as of 22/10/2026 | 75 kB 975 lines |
 MiMo-V2.6-Pro thinking Xiaomi Model profile → | broken fixed version → | 0 after fix 3 | 0/8 after fix 0/8 | – after fix 29 | – / 0 after fix 0 / 0 | 13 min 34 s | 102,520 | $0.089 prices as of 25/10/2026 | 81 kB 1,455 lines |
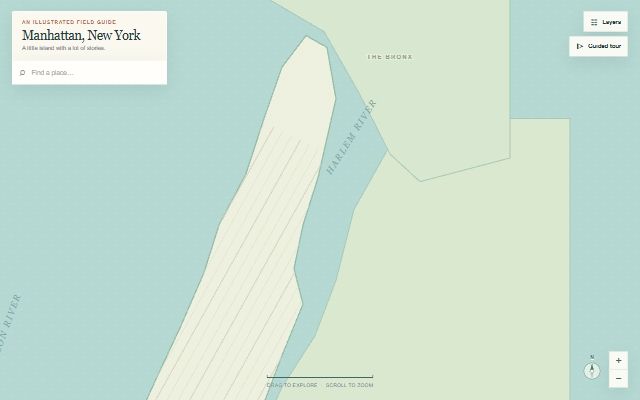 GPT-6.1 Terra medium OpenAI Model profile → | broken fixed version → | 0 after fix 80 | 0/8 after fix 6.5/8 | 69 after fix 94 | 0 / 0 after fix 67 / 80 | 3 min 12 s | 17,688 | $0.087 prices as of 26/10/2026 | 45 kB 524 lines |
 Mistral Large 4 1029 medium Mistral Model profile → | broken fixed version → | 0 after fix 53 | 0/8 after fix 3.5/8 | 96 after fix 96 | 81 / 0 after fix 81 / 30 | 6 min 32 s | 58,492 | $0.12 prices as of 31/10/2026 | 36 kB 595 lines |
Cost = tokens priced with the API price list valid on the date shown next to the cost (prices change). ≈ = estimate (only the total token count is known), no ≈ = exact from input / output tokens. “Loads” = the page opens without errors; technical health also checks behaviour during use – judge the quality in the viewer.
Evaluation
40 outputs from 40 models for the same zero-shot prompt – each one the model's first answer, published unedited.
- 4.4/8average score
- 30/40working outputs
- 90/100avg. technical health
- 61/100avg. UX
Broken (do not run): 10, 8 of them with a copy fixed by the same model. The average checklist score is 4.4/8 (a broken output scores 0), 5.8/8 among working ones. Best result in our test: Claude Sonnet 5.5, GPT-6 Astra, Gemini 4 Argon and 1 more – 8/8. Weakest working: Gemini 3.1 Flash-Lite – 2.5/8.
How the 8 requirements were met
From 30 working outputs: ✓ met, ½ partly, ✗ missing. Rate = (✓ + ½ × 0.5) / number of outputs.
| Requirement | ✓ | ½ | ✗ | Rate |
|---|---|---|---|---|
| Recognizable Manhattan, rivers, neighbouring areas, Roosevelt Island, bridges | 7 | 17 | 6 | 52 % |
| Rotated street grid, avenues, major cross streets, Broadway, irregular Lower Manhattan | 8 | 14 | 8 | 50 % |
| Detailed Central Park (Reservoir, lakes, lawns, Ramble, Mall, Bethesda, Belvedere, Zoo, paths) | 15 | 11 | 4 | 68 % |
| 30+ landmarks roughly in place, categories with icons | 19 | 11 | 0 | 82 % |
| Pan & zoom with mouse, wheel, pinch, buttons, keyboard; zoom-dependent labels | 19 | 11 | 0 | 82 % |
| Hover tooltip, info card on click, search with suggestions and fly-to | 18 | 12 | 0 | 80 % |
| Layer toggles, scale bar, compass, guided tour | 17 | 13 | 0 | 78 % |
| Drawn in code, full window, resize & high-DPI, runs without errors | 25 | 5 | 0 | 92 % |
Strengths
The requirements the models met best – quotes from the reviewer's verdicts:
Drawn in code, full window, resize & high-DPI, runs without errors · 92 % met
Code-drawn, full window, DPR-aware resize, renders fine.
– Claude Sonnet 5.5Code-drawn SVG, full window, resize handled, crisp high-DPI.
– GPT-6 Astra
30+ landmarks roughly in place, categories with icons · 82 % met
Over 30 correctly placed landmarks with category icons.
– Claude Sonnet 5.555 landmarks at real coordinates with category icons.
– GPT-6 Astra
Typical mistakes
The requirements the models most often missed or met only partly:
Rotated street grid, avenues, major cross streets, Broadway, irregular Lower Manhattan · 50 % met
Streets have no stroke style; invisible on the map.
– DeepSeek V4.1 Flash 0910Streets render as black wedges; no visible grid.
– MiniMax M3.1 Flash
Recognizable Manhattan, rivers, neighbouring areas, Roosevelt Island, bridges · 52 % met
Manhattan is an extremely thin sliver (1:37), the neighbours are grey slabs.
– Hy4 previewCrude polygon, rectangle neighbours, and the map is upside down.
– Mistral Medium 3.5
Detailed Central Park (Reservoir, lakes, lawns, Ramble, Mall, Bethesda, Belvedere, Zoo, paths) · 68 % met
Detailed park data renders as an undifferentiated black area.
– DeepSeek V4.1 Flash 0910Park features defined but render invisibly tiny in corner.
– DeepSeek V4 Pro
Agreement of two independent reviewers
The checklist of 40 outputs was filled in independently by two AI reviewers, Claude Opus 5.5 and Codex (GPT-6 Astra, medium). They agreed on 250 of 320 items (78 %). Average score by Claude 5.6/8, by Codex 5.2/8. Codex gave a lower score for 21, a higher one for 10 and the same for 9 outputs. They disagreed most often on: Recognizable Manhattan, rivers, neighbouring areas, Roosevelt Island, bridges (11×), Pan & zoom with mouse, wheel, pinch, buttons, keyboard; zoom-dependent labels (11×), Detailed Central Park (Reservoir, lakes, lawns, Ramble, Mall, Bethesda, Belvedere, Zoo, paths) (10×).
Where the reviewers disagree, the stricter (lower) verdict is proposed; the published score is approved by a human.
Objective tests
Measured by a tool, not by a person or an AI – so they are shown even before the scores are approved.
- Tech: average 90/100 from 38 measurements; highest GPT-6 Sol (100), lowest GPT-5.6 Luna (55). Measures Lighthouse, smoothness, errors during automated use, the mobile layout and whether the controls work.
- UX / UI: average 61/100 from 38 measurements; highest Gemini 3.6 Flash (89), lowest GPT-6.1 Terra (0). Measures control size, layout at 3 widths, keyboard, feedback and readability.