Which AI model built the best monitor test? Results of our test
Results of the same prompt side by side. Nothing runs on this page – click a row to open the output. Sort by clicking a column header; the best value is highlighted.
Short answer
- Best result in our test: Gemini 3.6 Flash – 8/8 requirements, overall score 98/100, cost $0.11, time 2 min 52 s.
- Cheapest result without a critical flaw (at least 6/8, no requirement failed outright): GLM-5.3-Flash – 7/8 for $0.030.
- 37 of 40 outputs ran on the first attempt (93 %).
Tested 12 Oct 2026 – 6 Nov 2026, one attempt for each of the 40 outputs, model versions are in the table. This is the result of our test, not a general measure of a model's reliability – another attempt may turn out differently. Time = from sending the prompt to the last token of the answer, thinking included (for runs in Claude Code the whole task incl. writing the file), fixes excluded. Cost = tokens × the public API price list as of the date at the model, fixes excluded; ≈ = an estimate when only the token total is known. It is not the amount actually paid – subscriptions, caching or discounts change it.
 Gemini 3.6 Flash medium Google Model profile → | loads | 98 | 8/8 | 100 | 97 / 90 | 2 min 52 s | 29,192 | $0.11 prices as of 17/10/2026 | 60 kB 1,804 lines |
 Claude Haiku 5.5 medium Anthropic Model profile → | loads | 97 | 8/8 | 97 | 100 / 80 | 7 min 13 s | 162,695 | ≈ $0.070 prices as of 06/10/2026 | 41 kB 1,084 lines |
 GPT-5.5 medium OpenAI Model profile → | loads | 97 | 8/8 | 100 | 98 / 80 | 2 min 21 s | 13,996 | $0.41 prices as of 17/10/2026 | 38 kB 830 lines |
 Grok 4.7 default xAI Model profile → | loads | 97 | 8/8 | 99 | 92 / 90 | 34 min 39 s | 176,955 | $1.05 prices as of 24/10/2026 | 123 kB 2,786 lines |
 Claude Opus 5.5 medium Anthropic Model profile → | loads | 96 | 8/8 | 98 | 97 / 80 | 14 min 00 s | 143,936 | ≈ $2.65 prices as of 06/10/2026 | 78 kB 1,452 lines |
 GPT-6.1 Sol medium OpenAI Model profile → | loads | 96 | 8/8 | 100 | 96 / 80 | 3 min 30 s | 139,105 | $0.12 prices as of 15/10/2026 | 25 kB 71 lines |
 GPT-6 Sol medium OpenAI Model profile → | loads | 96 | 8/8 | 100 | 90 / 80 | 2 min 15 s | 197,253 | $0.18 prices as of 15/10/2026 | 29 kB 147 lines |
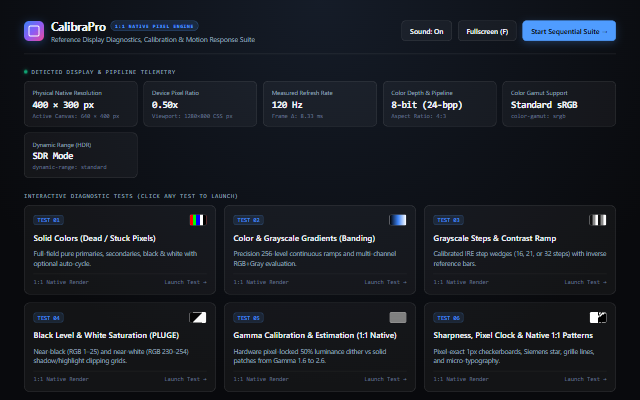 Gemini 4 Argon medium Google Model profile → | loads | 96 | 8/8 | 97 | 95 / 80 | 3 min 52 s | 26,835 | $0.27 prices as of 17/10/2026 | 75 kB 2,190 lines |
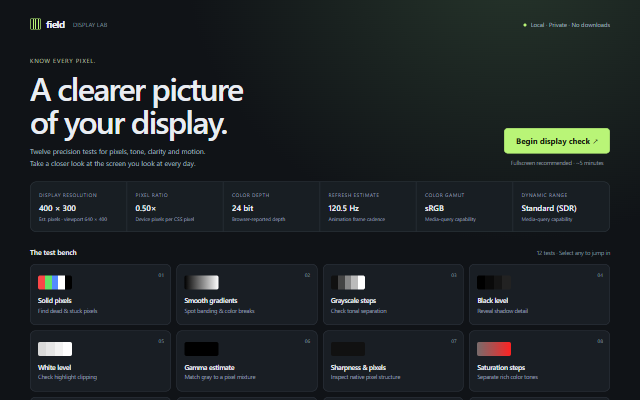 GPT-6 Astra medium OpenAI Model profile → | loads | 95 | 8/8 | 100 | 89 / 80 | 4 min 18 s | 161,987 | $0.78 prices as of 15/10/2026 | 31 kB 90 lines |
 Qwen3.8 Max thinking Alibaba Model profile → | loads | 95 | 8/8 | 99 | 88 / 80 | 20 min 24 s | 51,320 | $0.31 prices as of 22/10/2026 | 55 kB 1,112 lines |
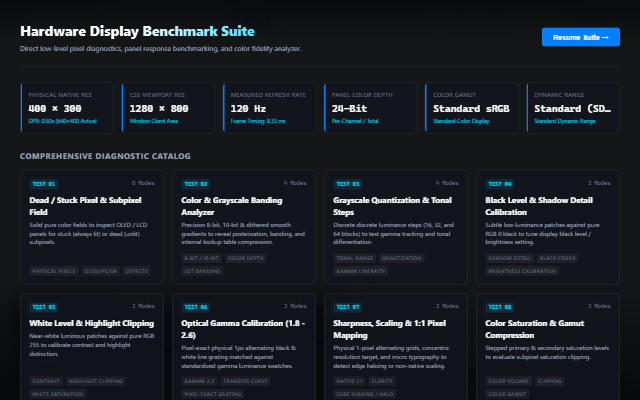 Gemini 3.8 Flash medium Google Model profile → | loads | 94 | 8/8 | 97 | 83 / 80 | 2 min 31 s | 28,036 | $0.10 prices as of 16/10/2026 | 66 kB 1,986 lines |
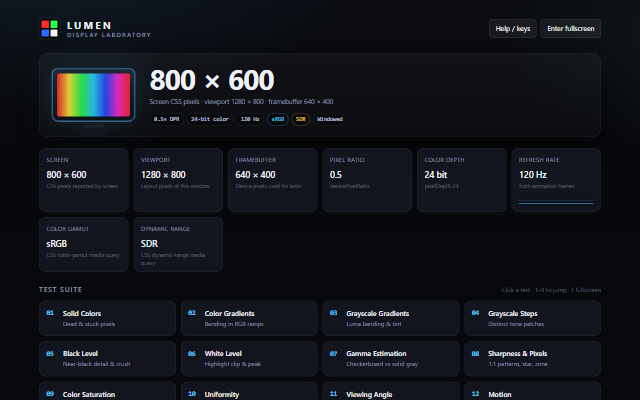 Grok 4.6 default xAI Model profile → | loads | 93 | 8/8 | 97 | 73 / 80 | 11 min 20 s | 49,470 | $0.29 prices as of 18/10/2026 | 61 kB 1,573 lines |
 DeepSeek V4.1 Flash 1017 high DeepSeek Model profile → | loads | 93 | 7.5/8 | 100 | 88 / 90 | 3 min 49 s | 62,962 | $0.038 prices as of 20/10/2026 | 51 kB 1,388 lines |
 Kimi K3 thinking Moonshot AI Model profile → | loads | 93 | 8/8 | 100 | 82 / 70 | 34 min 20 s | 61,396 | $0.92 prices as of 22/10/2026 | 39 kB 693 lines |
 GPT-6.1 Terra medium OpenAI Model profile → | loads | 93 | 7.5/8 | 100 | 85 / 90 | 2 min 11 s | 12,096 | $0.059 prices as of 26/10/2026 | 34 kB 527 lines |
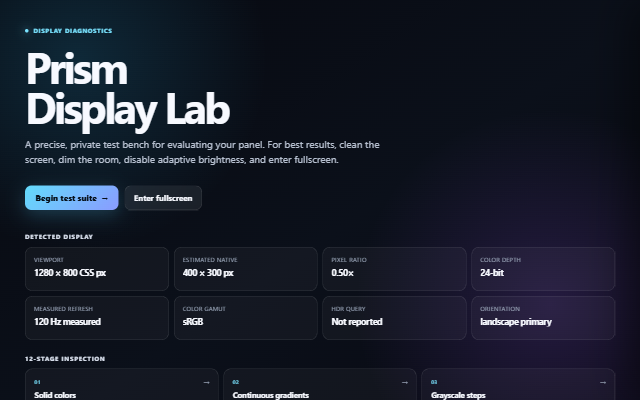 GPT-5.6 Sol medium OpenAI Model profile → | loads | 92 | 8/8 | 98 | 81 / 70 | 2 min 35 s | 237,349 | $0.36 prices as of 15/10/2026 | 29 kB 285 lines |
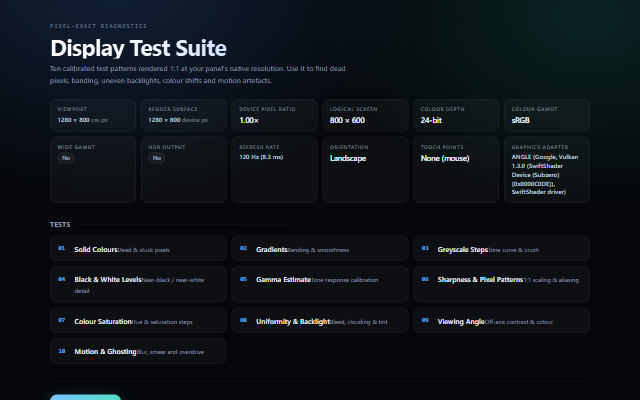 DeepSeek V4.1 Flash 0910 high DeepSeek Model profile → | loads | 91 | 7.5/8 | 93 | 92 / 80 | 4 min 33 s | 62,180 | $0.037 prices as of 16/10/2026 | 59 kB 1,783 lines |
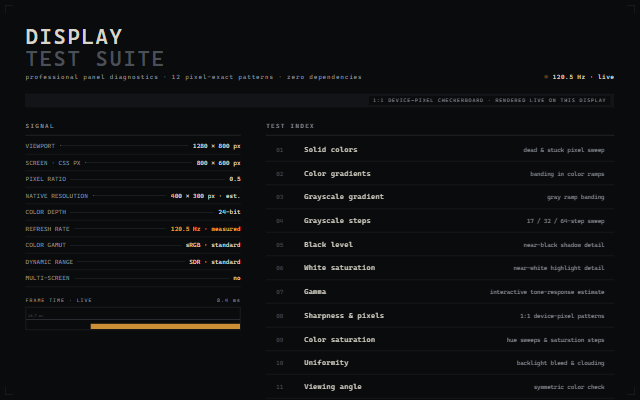 GLM 5.3 high Z.ai Model profile → | loads | 91 | 8/8 | 99 | 73 / 70 | 5 min 09 s | 60,356 | $0.26 prices as of 17/10/2026 | 43 kB 1,053 lines |
 Hy4 preview thinking Tencent Model profile → | loads | 91 | 7.5/8 | 97 | 88 / 80 | 6 min 19 s | 32,509 | $0.081 prices as of 06/11/2026 | 32 kB 651 lines |
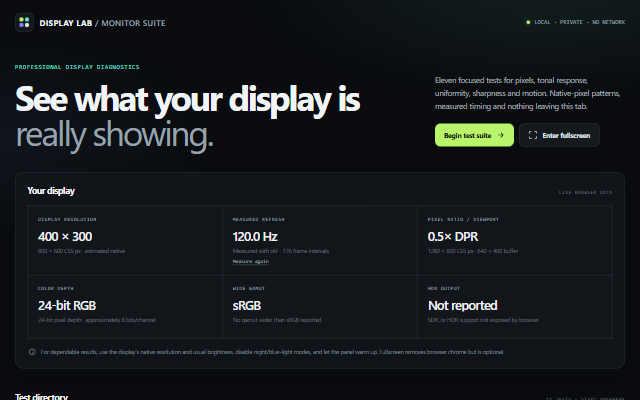 Kimi K3.1 Pro thinking Moonshot AI Model profile → | loads | 89 | 7.5/8 | 99 | 83 / 70 | 22 min 48 s | 51,758 | $0.51 prices as of 25/10/2026 | 81 kB 2,473 lines |
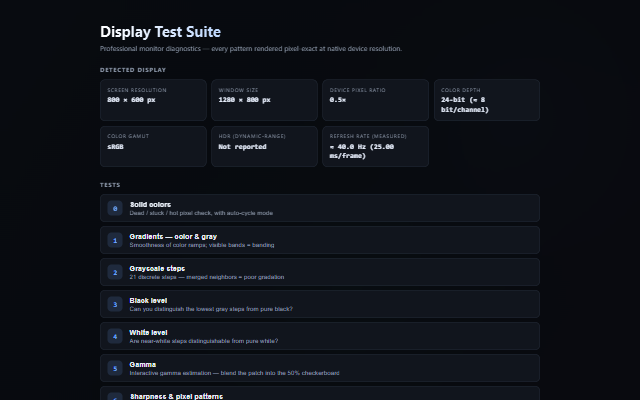 Mistral Large 4 1029 medium Mistral Model profile → | loads | 89 | 7/8 | 100 | 95 / 80 | 3 min 45 s | 27,325 | $0.057 prices as of 31/10/2026 | 31 kB 605 lines |
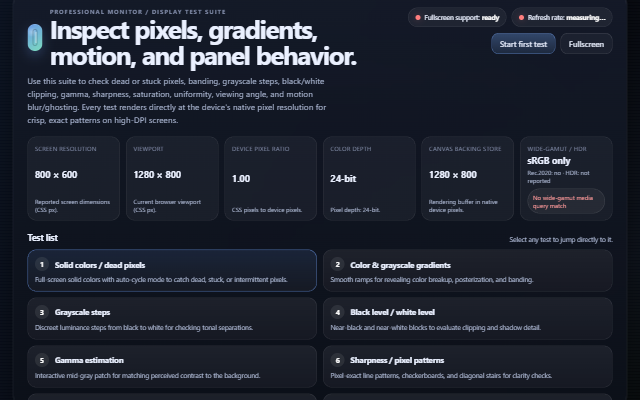 GPT-5.4 mini medium OpenAI Model profile → | loads | 88 | 7/8 | 100 | 87 / 80 | 4 min 24 s | 70,176 | $0.31 prices as of 17/10/2026 | 61 kB 2,097 lines |
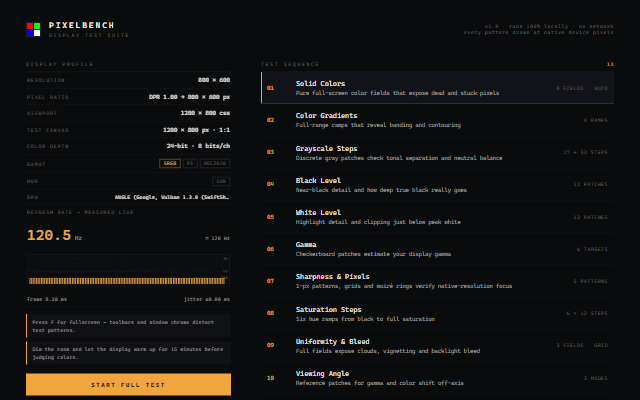 GLM-5.3-Flash high Z.ai Model profile → | loads | 87 | 7/8 | 99 | 83 / 80 | 4 min 53 s | 59,342 | $0.030 prices as of 31/10/2026 | 46 kB 1,046 lines |
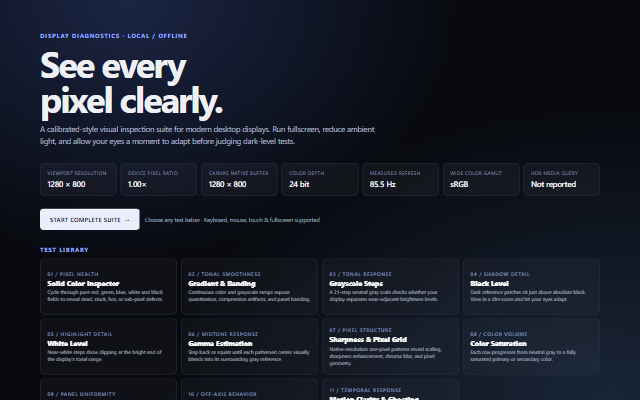 GPT-5.6 Terra medium OpenAI Model profile → | loads | 86 | 7/8 | 100 | 77 / 80 | 54 s | 7,257 | $0.083 prices as of 17/10/2026 | 21 kB 292 lines |
 MiniMax M3.1 Flash thinking MiniMax Model profile → | loads | 85 | 6.5/8 | 98 | 93 / 80 | 6 min 53 s | 53,651 | $0.032 prices as of 25/10/2026 | 83 kB 2,586 lines |
 MiMo-V2.6-Pro thinking Xiaomi Model profile → | loads | 85 | 6.5/8 | 100 | 94 / 80 | 19 min 55 s | 63,287 | $0.055 prices as of 25/10/2026 | 79 kB 1,588 lines |
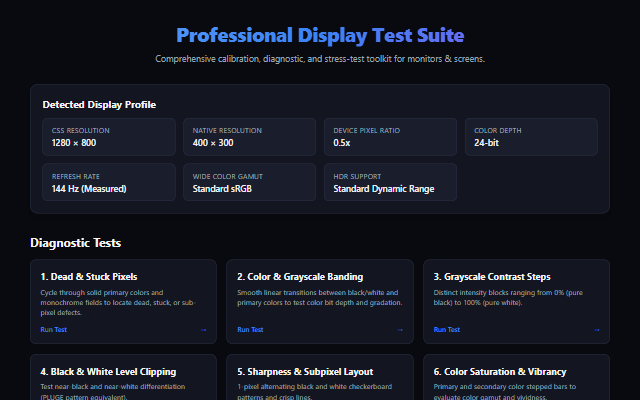 Gemini 3.5 Flash-Lite medium Google Model profile → | loads | 82 | 6/8 | 98 | 100 / 80 | 35 s | 12,257 | $0.030 prices as of 17/10/2026 | 35 kB 996 lines |
 Mistral Medium 3.5 high Mistral Model profile → | loads | 80 | 6/8 | 97 | 100 / 70 | 2 min 45 s | 27,944 | $0.21 prices as of 17/10/2026 | 33 kB 1,101 lines |
 Muse Wonder thinking Meta Model profile → | loads | 80 | 6/8 | 99 | 100 / 70 | 1 min 50 s | 18,079 | $0.36 prices as of 25/10/2026 | 47 kB 448 lines |
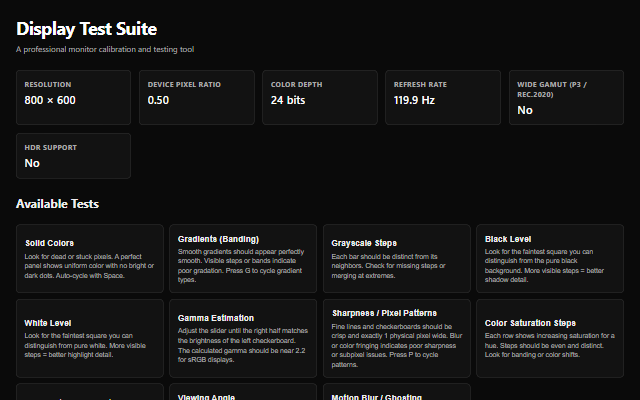 DeepSeek V4 Pro high DeepSeek Model profile → | loads | 79 | 7.5/8 | 75 | 0 / 100 | 3 min 05 s | 28,195 | $0.055 prices as of 16/10/2026 | 49 kB 1,229 lines |
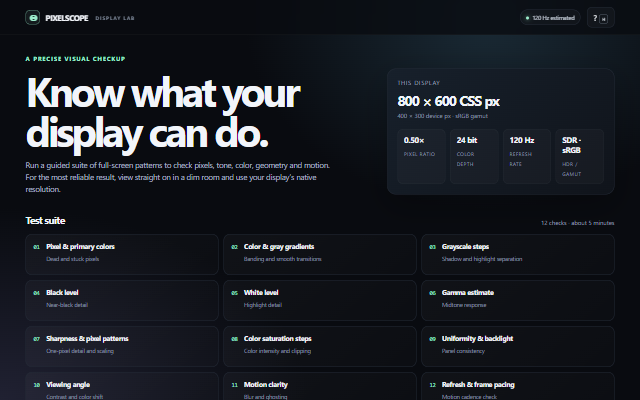 GPT-6 Luna medium OpenAI Model profile → | loads | 76 | 5.5/8 | 100 | 85 / 80 | 1 min 38 s | 265,172 | $0.00898 prices as of 15/10/2026 | 27 kB 70 lines |
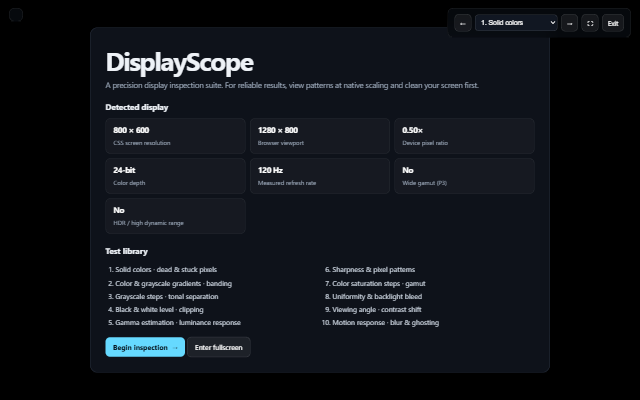 GPT-5.6 Luna medium OpenAI Model profile → | loads | 75 | 5.5/8 | 90 | 95 / 70 | 33 s | 4,786 | $0.00537 prices as of 17/10/2026 | 14 kB 109 lines |
 Gemma 4 31B default Google Model profile → | loads | 73 | 5/8 | 97 | 100 / 70 | 3 min 19 s | 7,450 | $0.00 prices as of 17/10/2026 | 25 kB 616 lines |
 Mistral Small 4 high Mistral Model profile → | loads | 55 | 3/8 | 98 | 94 / 60 | 1 min 39 s | 21,059 | $0.012 prices as of 17/10/2026 | 29 kB 942 lines |
 Gemini 3.1 Flash-Lite medium Google Model profile → | loads | 51 | 3/8 | 84 | 87 / 50 | 8 s | 3,331 | $0.00452 prices as of 17/10/2026 | 7 kB 178 lines |
 Codestral 25.08 default Mistral Model profile → | loads | 26 | 2.5/8 | 69 | 0 / 0 | 1 min 12 s | 9,739 | $0.00854 prices as of 17/10/2026 | 41 kB 1,076 lines |
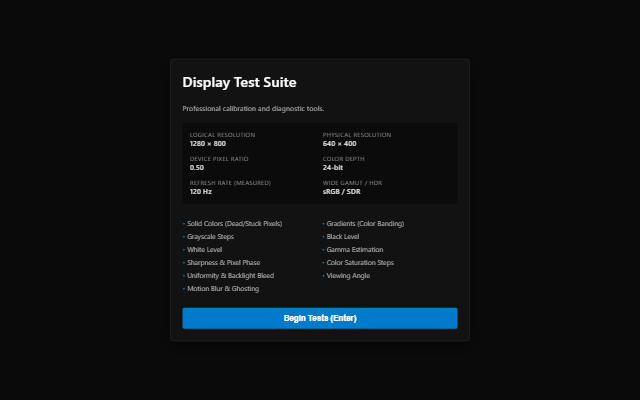 Gemini 3.1 Pro medium Google Model profile → | loads | 15 | 1/8 | 77 | 0 / 0 | 1 min 09 s | 10,723 | $0.12 prices as of 17/10/2026 | 26 kB 790 lines |
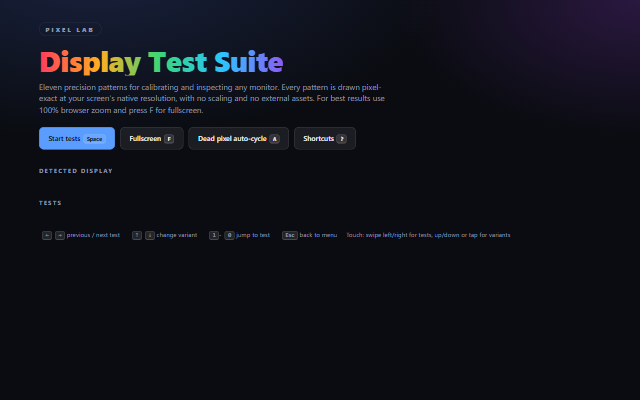 Claude Sonnet 5.5 medium Anthropic Model profile → | broken fixed version → | 0 after fix 97 | 0/8 after fix 8/8 | 71 after fix 100 | 0 / 0 after fix 98 / 80 | 7 min 05 s | 113,105 | ≈ $1.04 prices as of 06/10/2026 | 42 kB 684 lines |
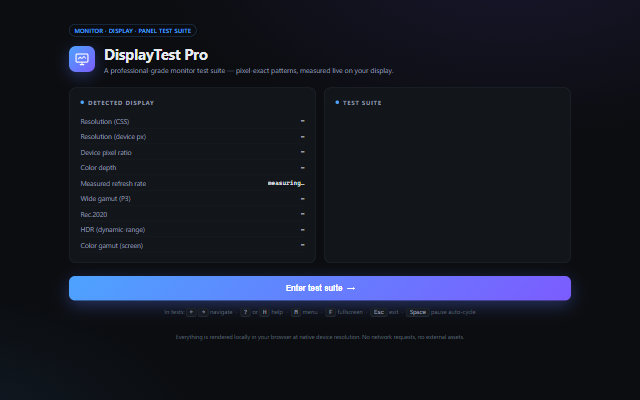 Mistral Large 4 Preview none Mistral Model profile → | broken fixed version → | 0 after fix 15 | 0/8 after fix 0/8 | 69 after fix 74 | 0 / 0 after fix 50 / 0 | 6 min 37 s | 21,760 | $0.045 prices as of 17/10/2026 | 67 kB 1,414 lines |
 Qwen3.6 27B thinking Alibaba Model profile → | broken fixed version → | 0 after fix 86 | 0/8 after fix 7/8 | – after fix 100 | – / 0 after fix 89 / 70 | 4 min 33 s | 15,591 | $0.031 prices as of 25/10/2026 | 45 kB 1,395 lines |
Cost = tokens priced with the API price list valid on the date shown next to the cost (prices change). ≈ = estimate (only the total token count is known), no ≈ = exact from input / output tokens. “Loads” = the page opens without errors; technical health also checks behaviour during use – judge the quality in the viewer.
Evaluation
40 outputs from 40 models for the same zero-shot prompt – each one the model's first answer, published unedited.
- 6.2/8average score
- 37/40working outputs
- 95/100avg. technical health
- 78/100avg. UX
Broken (do not run): 3, 3 of them with a copy fixed by the same model. The average checklist score is 6.2/8 (a broken output scores 0), 6.7/8 among working ones. Best result in our test: Claude Opus 5.5, Claude Haiku 5.5, GPT-6 Astra and 12 more – 8/8. Weakest working: Gemini 3.1 Pro – 1/8.
How the 8 requirements were met
From 37 working outputs: ✓ met, ½ partly, ✗ missing. Rate = (✓ + ½ × 0.5) / number of outputs.
| Requirement | ✓ | ½ | ✗ | Rate |
|---|---|---|---|---|
| Start screen with display info (resolution, DPR, color depth, measured Hz, gamut/HDR) and test list | 33 | 4 | 0 | 95 % |
| Solid colors for dead pixels with auto-cycle | 29 | 6 | 2 | 86 % |
| Color & gray gradients (banding) and grayscale steps | 31 | 5 | 1 | 91 % |
| Black & white level, gamma estimation | 24 | 9 | 4 | 77 % |
| Sharpness & pixel patterns exact at native resolution incl. high-DPI | 25 | 9 | 3 | 80 % |
| Saturation, uniformity / backlight bleed, viewing angle | 28 | 7 | 2 | 85 % |
| Motion test (blur, ghosting) at several speeds | 28 | 7 | 2 | 85 % |
| Explanation per test, keyboard / mouse / touch navigation, fullscreen, auto-hiding UI and cursor | 20 | 16 | 1 | 76 % |
Strengths
The requirements the models met best – quotes from the reviewer's verdicts:
Start screen with display info (resolution, DPR, color depth, measured Hz, gamut/HDR) and test list · 95 % met
Start screen shows resolution, DPR, depth, Hz, gamut/HDR, test list.
– Claude Opus 5.5Start screen shows display info, measured Hz and test list.
– Claude Haiku 5.5
Color & gray gradients (banding) and grayscale steps · 91 % met
Gray and color ramps without dithering plus grayscale steps.
– Claude Opus 5.5Gray and hue ramps, dithered variants, grayscale steps.
– Claude Haiku 5.5
Typical mistakes
The requirements the models most often missed or met only partly:
Explanation per test, keyboard / mouse / touch navigation, fullscreen, auto-hiding UI and cursor · 76 % met
Test controls unreachable; start crashes.
– Gemini 3.1 ProSolid UX, but sub-mode switching is keyboard-only.
– DeepSeek V4 Pro
Black & white level, gamma estimation · 77 % met
No near-black/white patches or real gamma estimation.
– Mistral Small 4Single dark patch only; no gamma test.
– Gemini 3.1 Flash-Lite
Sharpness & pixel patterns exact at native resolution incl. high-DPI · 80 % met
Not pixel-exact; only coarse checkerboard.
– Mistral Small 4Pixel patterns freeze page; sharpness is coarse.
– Codestral 25.08
Agreement of two independent reviewers
The checklist of 40 outputs was filled in independently by two AI reviewers, Claude Opus 5.5 and Codex (GPT-6 Astra, medium). They agreed on 272 of 320 items (85 %). Average score by Claude 6.6/8, by Codex 6.2/8. Codex gave a lower score for 21, a higher one for 5 and the same for 14 outputs. They disagreed most often on: Explanation per test, keyboard / mouse / touch navigation, fullscreen, auto-hiding UI and cursor (13×), Sharpness & pixel patterns exact at native resolution incl. high-DPI (10×), Saturation, uniformity / backlight bleed, viewing angle (6×).
Where the reviewers disagree, the stricter (lower) verdict is proposed; the published score is approved by a human.
Objective tests
Measured by a tool, not by a person or an AI – so they are shown even before the scores are approved.
- Tech: average 95/100 from 39 measurements; highest GPT-6 Astra (100), lowest Mistral Large 4 Preview (69). Measures Lighthouse, smoothness, errors during automated use, the mobile layout and whether the controls work.
- UX / UI: average 78/100 from 39 measurements; highest Claude Haiku 5.5 (100), lowest Mistral Large 4 Preview (0). Measures control size, layout at 3 widths, keyboard, feedback and readability.