Model comparison
Results of the same prompt side by side. Nothing runs on this page – click a row to open the output. Sort by clicking a column header; the best value is highlighted.
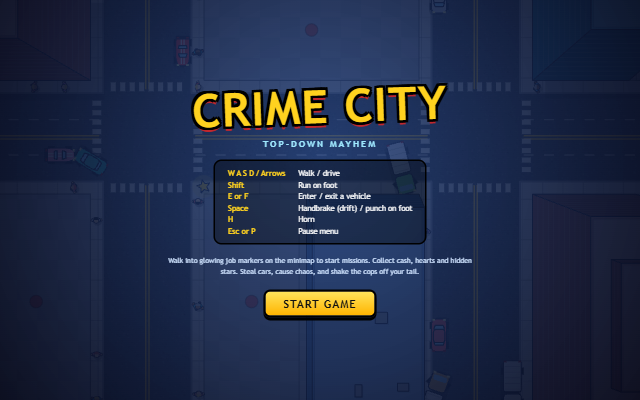 Claude Sonnet 5.5 medium Anthropic Model profile → | loads | 99 | 8/8 | 100 | 100 / 90 | 17 min 03 s | 196,634 | ≈ $1.81 prices as of 06/10/2026 | 88 kB 1,648 lines |
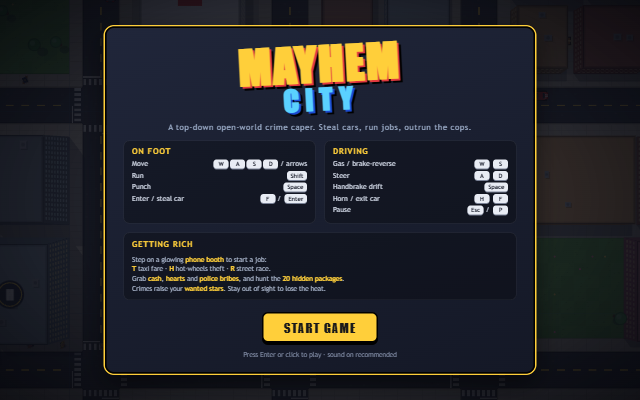 Claude Opus 5.5 medium Anthropic Model profile → | loads | 97 | 8/8 | 99 | 100 / 80 | 67 min 54 s | 214,420 | ≈ $3.95 prices as of 06/10/2026 | 106 kB 2,003 lines |
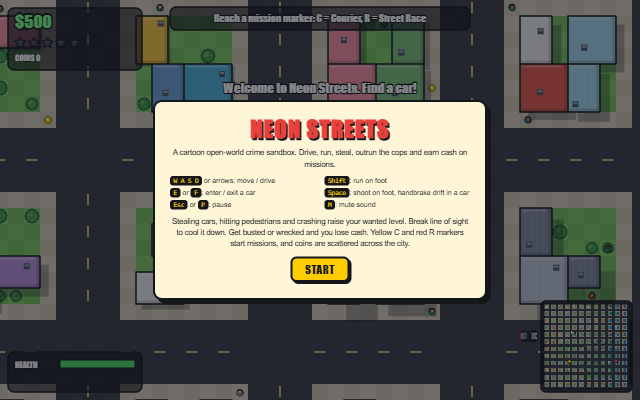 Claude Haiku 5.5 medium Anthropic Model profile → | loads | 96 | 8/8 | 100 | 100 / 70 | 31 min 13 s | 234,719 | ≈ $0.11 prices as of 06/10/2026 | 54 kB 1,517 lines |
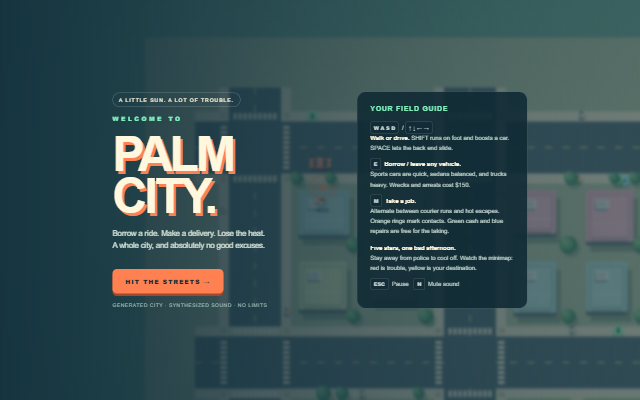 GPT-6 Astra medium OpenAI Model profile → | loads | 92 | 8/8 | 100 | 77 / 70 | 11 min 09 s | 295,761 | $2.06 prices as of 15/10/2026 | 38 kB 124 lines |
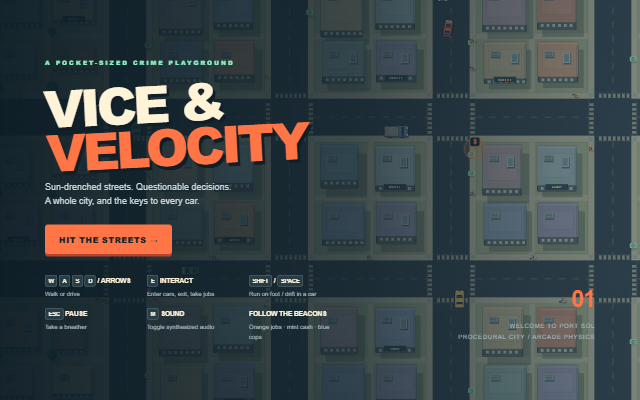 GPT-6.1 Sol medium OpenAI Model profile → | loads | 92 | 8/8 | 100 | 79 / 70 | 8 min 19 s | 203,096 | $0.26 prices as of 15/10/2026 | 49 kB 146 lines |
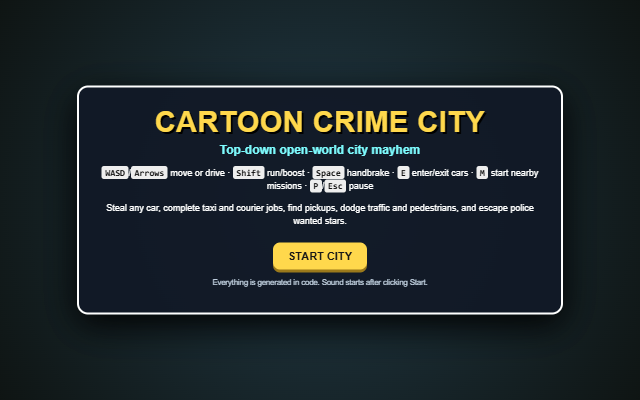 GPT-5.5 medium OpenAI Model profile → | loads | 90 | 7.5/8 | 98 | 100 / 60 | 1 min 51 s | 11,362 | $0.33 prices as of 17/10/2026 | 24 kB 321 lines |
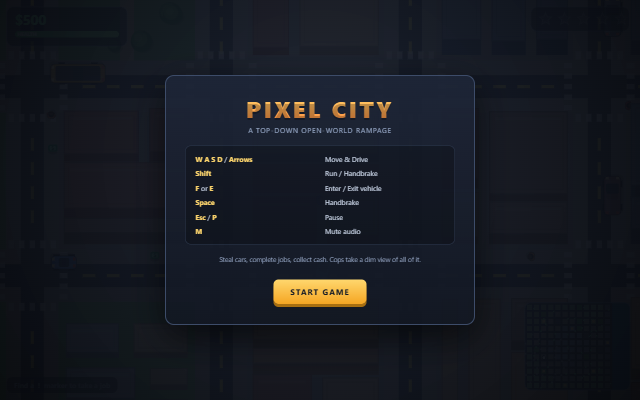 DeepSeek V4.1 Flash high DeepSeek Model profile → | loads | 90 | 7.5/8 | 100 | 100 / 60 | 5 min 24 s | 74,083 | $0.044 prices as of 16/10/2026 | 79 kB 2,450 lines |
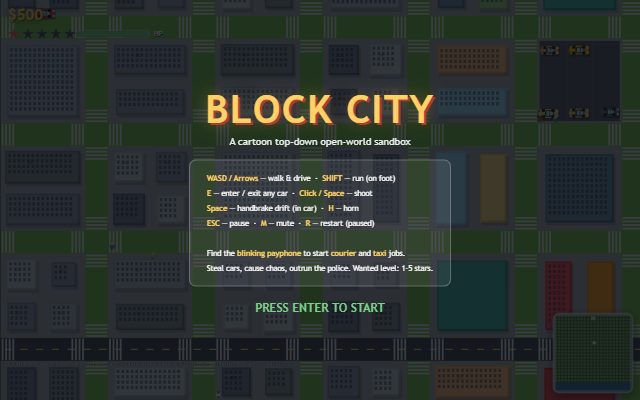 Mistral Large 4 none Mistral Model profile → | loads | 90 | 7.5/8 | 100 | 100 / 60 | 36 min 41 s | 90,741 | $0.19 prices as of 17/10/2026 | 65 kB 1,679 lines |
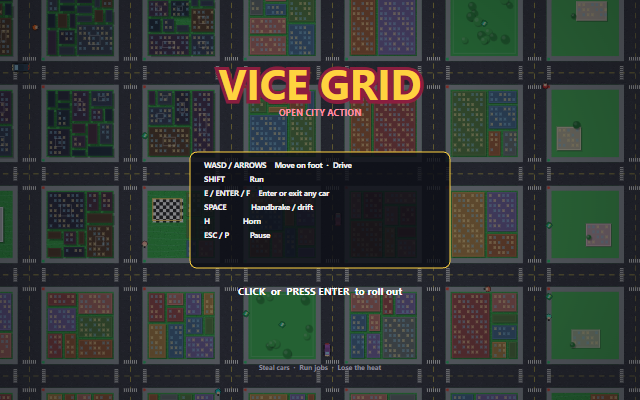 Grok 4.6 default xAI Model profile → | loads | 89 | 7.5/8 | 57 | 100 / 80 | 19 min 19 s | 77,762 | $0.46 prices as of 18/10/2026 | 66 kB 2,115 lines |
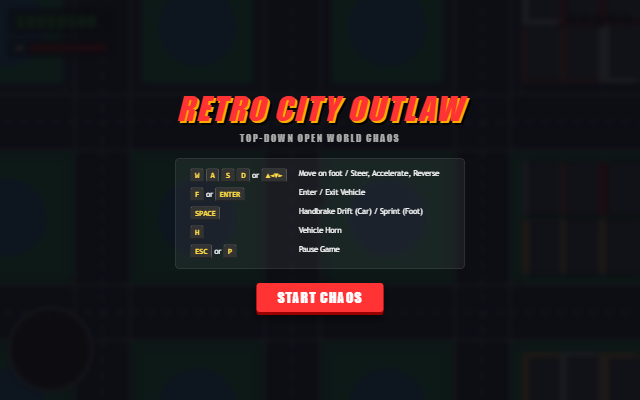 Gemini 3.8 Flash medium Google Model profile → | loads | 88 | 7/8 | 98 | 100 / 70 | 3 min 10 s | 27,927 | $0.10 prices as of 16/10/2026 | 68 kB 2,198 lines |
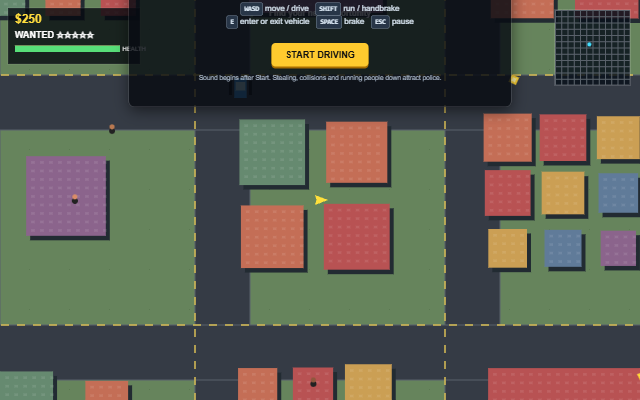 GPT-5.6 Terra medium OpenAI Model profile → | loads | 75 | 5.5/8 | 99 | 100 / 60 | 49 s | 6,923 | $0.079 prices as of 17/10/2026 | 17 kB 221 lines |
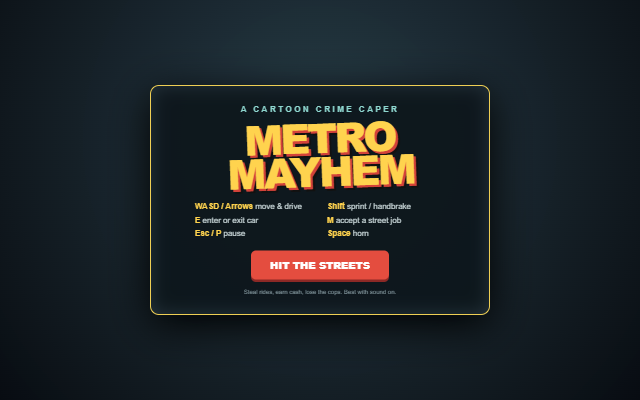 GPT-5.6 Sol medium OpenAI Model profile → | loads | 63 | 6/8 | 88 | 33 / 30 | 2 min 29 s | 271,508 | $0.34 prices as of 15/10/2026 | 21 kB 78 lines |
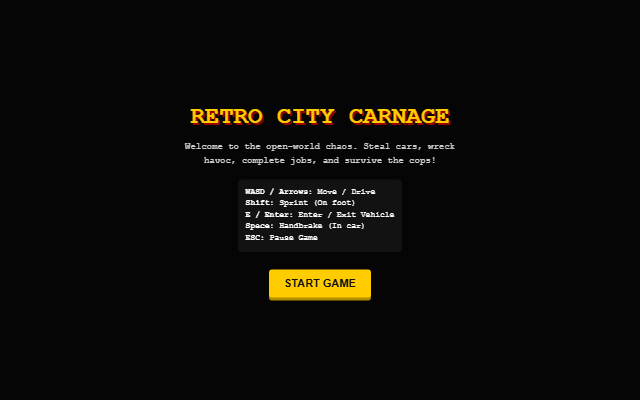 Gemini 3.5 Flash-Lite medium Google Model profile → | loads | 63 | 4/8 | 100 | 100 / 50 | 33 s | 11,866 | $0.029 prices as of 17/10/2026 | 31 kB 937 lines |
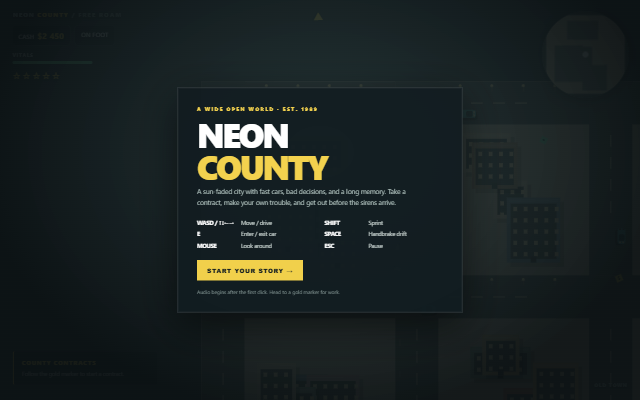 GPT-6 Luna medium OpenAI Model profile → | loads | 55 | 4.5/8 | 88 | 33 / 50 | 1 min 26 s | 229,923 | $0.00819 prices as of 15/10/2026 | 23 kB 56 lines |
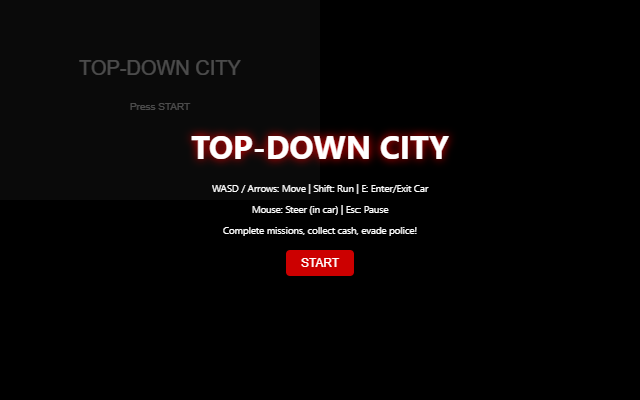 DeepSeek V4 Pro high DeepSeek Model profile → | loads | 51 | 4/8 | 90 | 33 / 50 | 2 min 26 s | 22,494 | $0.044 prices as of 16/10/2026 | 54 kB 1,276 lines |
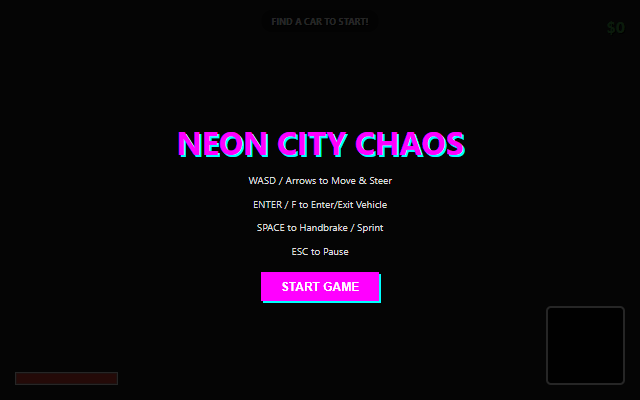 Gemma 4 31B default Google Model profile → | loads | 46 | 3.5/8 | 88 | 33 / 40 | 4 min 49 s | 10,931 | $0.00 prices as of 17/10/2026 | 31 kB 846 lines |
 Codestral 25.08 default Mistral Model profile → | loads | 38 | 4/8 | 84 | 0 / 0 | 2 min 07 s | 17,364 | $0.015 prices as of 17/10/2026 | 81 kB 2,050 lines |
 Gemini 4 Argon medium Google Model profile → | loads | 35 | 1.5/8 | 81 | 33 / 70 | 5 min 20 s | 35,884 | $0.35 prices as of 17/10/2026 | 98 kB 2,738 lines |
 Mistral Medium 3.5 high Mistral Model profile → | loads | 26 | 2.5/8 | 76 | 0 / 0 | 4 min 09 s | 40,966 | $0.30 prices as of 17/10/2026 | 45 kB 1,510 lines |
 Gemini 3.1 Flash-Lite medium Google Model profile → | loads | 12 | 0.5/8 | 83 | 0 / 0 | 8 s | 2,957 | $0.00385 prices as of 17/10/2026 | 5 kB 160 lines |
 Gemini 3.1 Pro medium Google Model profile → | loads | 11 | 0.5/8 | 76 | 0 / 0 | 2 min 06 s | 20,665 | $0.24 prices as of 17/10/2026 | 51 kB 1,257 lines |
 GPT-6 Sol medium OpenAI Model profile → | broken fixed version → | 0 after fix 86 | 0/8 after fix 7/8 | 70 after fix 99 | 0 / 0 after fix 89 / 70 | 3 min 11 s | 441,896 | $0.29 prices as of 15/10/2026 | 39 kB 215 lines |
 GPT-5.6 Luna medium OpenAI Model profile → | broken fixed version → | 0 after fix 12 | 0/8 after fix 0/8 | 74 after fix 74 | 33 / 0 after fix 33 / 0 | 35 s | 5,357 | $0.00598 prices as of 17/10/2026 | 13 kB 101 lines |
 GPT-5.4 mini medium OpenAI Model profile → | broken fixed version → | 0 after fix 7 | 0/8 after fix 0/8 | 69 after fix 69 | 0 / 0 after fix 0 / 0 | 7 min 09 s | 108,599 | $0.49 prices as of 17/10/2026 | 81 kB 2,547 lines |
 Mistral Small 4 high Mistral Model profile → | broken fixed version → | 0 after fix 11 | 0/8 after fix 0.5/8 | 29 after fix 73 | 0 / 0 after fix 0 / 0 | 1 min 39 s | 20,184 | $0.012 prices as of 17/10/2026 | 30 kB 976 lines |
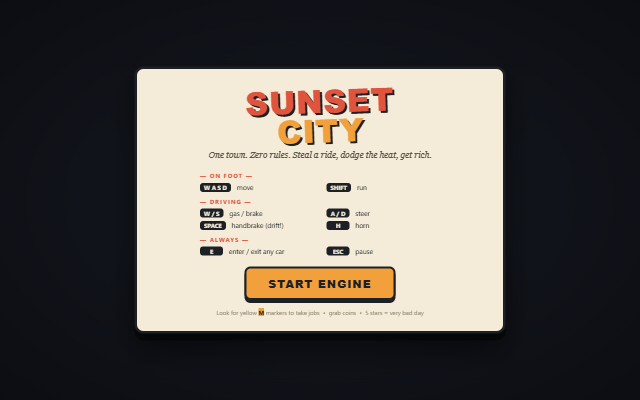 GLM 5.3 high Z.ai Model profile → | broken fixed version → | 0 after fix 67 | 0/8 after fix 4/8 | 69 after fix 99 | 0 / 0 after fix 100 / 80 | 7 min 11 s | 73,508 | $0.32 prices as of 17/10/2026 | 82 kB 1,884 lines |
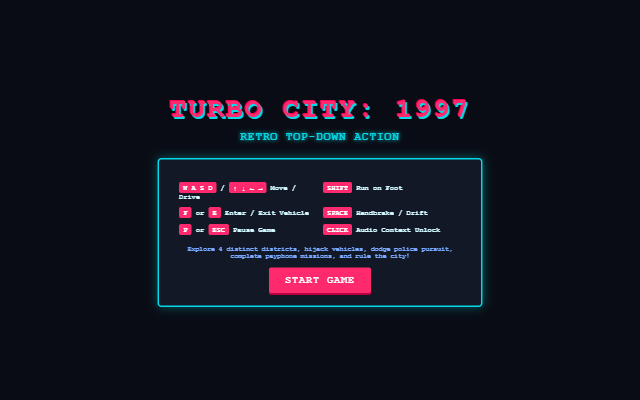 Gemini 3.6 Flash medium Google Model profile → | broken fixed version → | 0 after fix 49 | 0/8 after fix 3.5/8 | 67 after fix 87 | 0 / 0 after fix 33 / 60 | 1 min 52 s | 21,205 | $0.078 prices as of 17/10/2026 | 42 kB 1,360 lines |
Cost = tokens priced with the API price list valid on the date shown next to the cost (prices change). ≈ = estimate (only the total token count is known), no ≈ = exact from input / output tokens. “Loads” = the page opens without errors; technical health also checks behaviour during use – judge the quality in the viewer.
Evaluation
27 outputs from 27 models for the same zero-shot prompt – each one the model's first answer, published unedited.
- 4.2/8average score
- 21/27working outputs
- 85/100avg. technical health
- 50/100avg. UX
Broken (do not run): 6, 6 of them with a copy fixed by the same model. The average checklist score is 4.2/8 (a broken output scores 0), 5.4/8 among working ones. Best: Claude Opus 5.5, Claude Haiku 5.5, Claude Sonnet 5.5 and 2 more – 8/8. Weakest working: Gemini 3.1 Pro, Gemini 3.1 Flash-Lite – 0.5/8.
How the 8 requirements were met
From 21 working outputs: ✓ met, ½ partly, ✗ missing. Rate = (✓ + ½ × 0.5) / number of outputs.
| Requirement | ✓ | ½ | ✗ | Rate |
|---|---|---|---|---|
| Procedural city Procedural city: roads, junctions, sidewalks, varied buildings, parks + another district; camera follows and zooms out with speed |
9 | 10 | 2 | 67 % |
| Walk & run, enter and exit any car | 12 | 3 | 6 | 64 % |
| 3+ vehicle types with different handling, drift, collisions, visible damage | 10 | 7 | 4 | 64 % |
| Traffic in lanes turning at junctions, pedestrians on sidewalks fleeing danger | 8 | 8 | 5 | 57 % |
| Wanted 1–5 stars, escalating police, escaping lowers it, busted / wrecked costs money and respawns | 10 | 7 | 4 | 64 % |
| 2+ mission types with rewards, collectible pickups | 11 | 7 | 3 | 69 % |
| HUD HUD: money, stars, health, objective with arrow, minimap |
12 | 7 | 2 | 74 % |
| Web Audio sounds (engine, crash, siren), start screen with controls, pause menu | 13 | 8 | 0 | 81 % |
Strengths
The requirements the models met best – quotes from the reviewer's verdicts:
Web Audio sounds (engine, crash, siren), start screen with controls, pause menu · 81 % met
Synth engine, crash, siren sounds; start screen and pause menu.
– Claude Opus 5.5Synthesized engine/crash/siren, start screen and pause menu present.
– Claude Haiku 5.5
HUD · 74 % met
HUD shows money, stars, health, objective arrow, minimap.
– Claude Opus 5.5HUD has money, stars, health, objective arrow and minimap.
– Claude Haiku 5.5
Typical mistakes
The requirements the models most often missed or met only partly:
Traffic in lanes turning at junctions, pedestrians on sidewalks fleeing danger · 57 % met
Traffic is parked, pedestrians wander off sidewalks
– Gemini 3.5 Flash-LiteTraffic and pedestrian code has crash bugs
– Mistral Medium 3.5
Wanted 1–5 stars, escalating police, escaping lowers it, busted / wrecked costs money and respawns · 64 % met
Police spawning triggers a crash
– Mistral Medium 3.5Wanted system coded, but unreachable in play.
– Gemini 4 Argon
3+ vehicle types with different handling, drift, collisions, visible damage · 64 % met
Vehicle types exist, but driving throws an error
– Mistral Medium 3.5Cars, drift and damage coded but unreachable after crash.
– Gemini 4 Argon
Agreement of two independent reviewers
The checklist of 27 outputs was filled in independently by two AI reviewers, Claude Opus 5.5 and Codex (GPT-6 Astra, medium). They agreed on 179 of 216 items (83 %). Average score by Claude 4.8/8, by Codex 4.5/8. Codex gave a lower score for 10, a higher one for 7 and the same for 10 outputs. They disagreed most often on: Walk & run, enter and exit any car (9×), Wanted 1–5 stars, escalating police, escaping lowers it, busted / wrecked costs money and respawns (7×), Web Audio sounds (engine, crash, siren), start screen with controls, pause menu (6×).
Where the reviewers disagree, the stricter (lower) verdict is proposed; the published score is approved by a human.
Objective tests
Measured by a tool, not by a person or an AI – so they are shown even before the scores are approved.
- Tech: average 85/100 from 27 measurements; highest Claude Haiku 5.5 (100), lowest Mistral Small 4 (29). Measures Lighthouse, smoothness, errors during automated use, the mobile layout and whether the controls work.
- UX / UI: average 50/100 from 27 measurements; highest Claude Opus 5.5 (100), lowest Gemini 3.1 Flash-Lite (0). Measures control size, layout at 3 widths, keyboard, feedback and readability.